How do you preserve punctuation and formatting across writing systems? Preserve the semantic structure (paragraphs, lists, emphasis, placeholders, tables) while localizing punctuation and typography according to target-language conventions. Store text as Unicode, normalize consistently, use Unicode/CLDR rules for line breaks and locale formatting, and use bidi-compliant rendering for RTL scripts. Test the final target in the application or document rather than validating raw strings only.
| SEO title | Preserve Punctuation & Formatting Across Writing Systems |
|---|---|
| Slug | preserve-punctuation-formatting-writing-systems |
| Meta description | Learn how to preserve punctuation, line breaks, Unicode normalization, spacing, quotation marks, bidi text and formatting across multilingual writing systems. |
| Primary keyword | punctuation formatting multilingual translation |
| Search intent | How-to / Technical |
| Hero image | 195-punctuation-formatting-writing-systems.jpg |
| Hero alt text | Multilingual typography QA interface comparing punctuation, line breaks, spacing and script formatting across writing systems |
| Article body words | 1954 |
For production multilingual workflows, see our AI Translation service for the delivery path behind the guidance in this article.
Punctuation is not universal decoration.
Languages and writing systems differ in quotation marks, sentence punctuation, spacing, line breaking, digit formatting and bidirectional behavior. A translation pipeline that preserves source punctuation mechanically can make the target look foreign or even change how text is parsed and displayed.
At the same time, formatting contains structural information that must not be lost.
Unicode Standard Annex #14 defines line-breaking properties and algorithms for Unicode text, while UAX #9 governs bidirectional text.
Punctuation is language-specific
Examples of variation:
- quotation marks;
- colon spacing;
- comma/period;
- question marks.
French typography may place spaces differently from English around some punctuation.
Chinese and Japanese use full-width punctuation.
Arabic has script-specific punctuation forms.
Do not copy source punctuation blindly.
Quotation marks
English:
- “double quotes”
Other languages may use:
- « guillemets »;
- „low-high quotes”;
- corner brackets.
Style guide should define.
Use language-aware typography tools when available.
Apostrophes
Straight ASCII apostrophe and typographic apostrophe differ.
In some languages apostrophe is orthographic.
Do not normalize it away indiscriminately.
Sentence-ending punctuation
CJK scripts can use:
- 。
Arabic can use:
- Arabic question mark ؟.
A translation model should output target punctuation.
QA can detect source punctuation leftovers.
Full-width characters
East Asian typography often uses full-width punctuation.
Width affects:
- layout;
- line breaking.
Do not convert all punctuation to ASCII.
Spaces
Some writing systems do not use spaces between every word.
Chinese/Japanese:
- normal prose lacks Western word spaces.
Thai has its own word/line-breaking behavior.
Do not insert spaces based on source tokenization.
Line breaking
Breaking lines after a fixed character count is unsafe.
Unicode UAX #14 defines line-break classes and algorithms designed to support appropriate break opportunities across writing systems.
Applications should use internationalized layout engines.
Word segmentation
Line breaking does not always equal word segmentation.
CJK line breaks can occur between characters according to rules.
Thai may need dictionary segmentation.
Translation pipelines should not hard-code English whitespace assumptions.
Non-breaking spaces
Some typography uses non-breaking spaces around:
- units;
- punctuation;
- names.
Preserve semantic non-breaking behavior where required.
Unicode normalization
Visually identical text can have different code-point sequences.
Example:
- precomposed accented character;
- base character + combining mark.
Normalize consistently, commonly NFC for many systems, unless another requirement exists.
This improves:
- search;
- QA;
- term matching.
Combining marks
Diacritics can be:
- accent;
- tone.
Do not detach or reorder combining marks incorrectly.
This is important for:
- Yoruba;
- Vietnamese;
- Indic scripts.
Bidirectional formatting
RTL text can contain LTR:
- numbers;
- URLs.
Use Unicode bidi algorithm and semantic direction markup.
Do not reverse text.
Paragraph structure
Preserve:
- paragraphs;
- headings.
Do not collapse into one block.
Paragraph boundaries influence readability and translation context.
Lists
List markers vary.
Preserve semantic list structure in HTML/DOCX.
Let target renderer handle indentation/direction.
Do not embed manual bullets inside plain strings where avoidable.
Numbered lists
Numbers may use locale-specific digits.
But numbering sequence should remain.
For legal documents, clause identifiers may need exact preservation.
Emphasis
Bold/italic can carry meaning.
Preserve formatting tags around translated phrase.
The target word order may move the emphasized concept.
Do not blindly keep emphasis at same character offset.
Placeholders
Protect:
- {name};
- %s.
Formatting pipeline must distinguish programmatic syntax from punctuation.
HTML/XML
Parse structure.
Do not translate markup.
Translate text nodes/attributes explicitly marked.
Validate after.
Markdown
Protect:
- links;
- code fences.
Translate link text but not URL unless required.
Tables
Keep cell boundaries.
Punctuation inside cell can localize.
Numeric formats need locale rules.
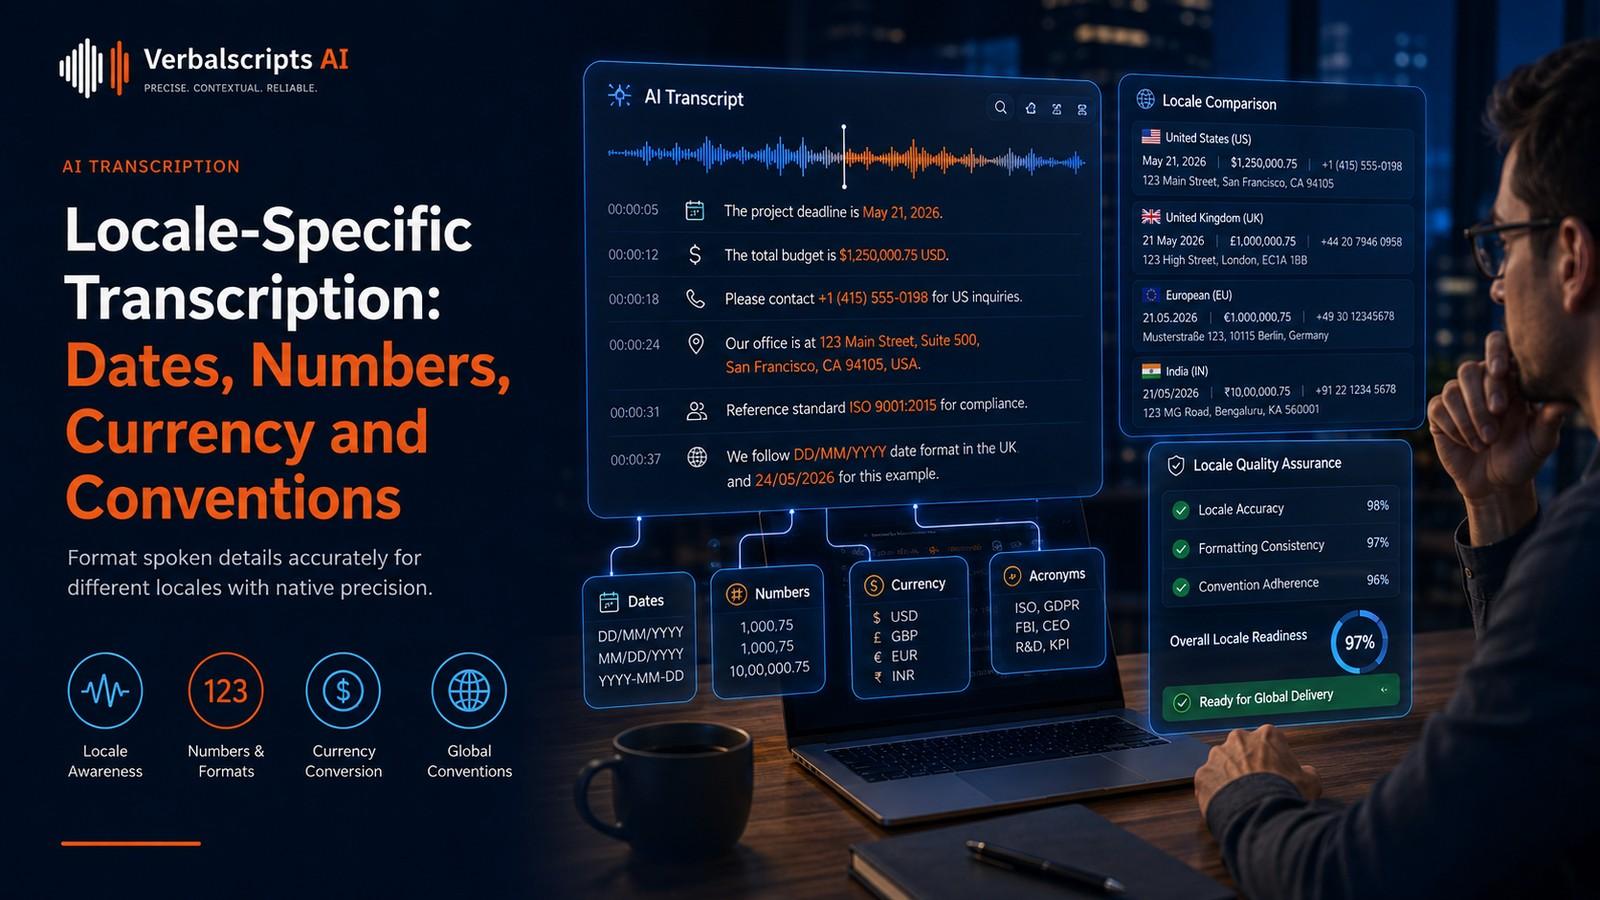
Dates and numbers
CLDR defines locale data for:
- separators;
- currencies.
Use formatters rather than translating dynamic values as strings.
Typography fonts
Script needs correct font coverage.
Fallback can change:
- line height;
- width.
Test layout.
CJK font fallback
A Latin brand font may not include Han characters.
Choose approved CJK fallback.
Avoid mixed glyph style across sentence.
Indic scripts
Complex scripts require shaping engines.
Do not split grapheme clusters by byte/character assumptions.
Use Unicode-aware libraries.
Grapheme clusters
What users perceive as one character may consist of multiple code points.
Cursor, truncation and substring logic should be grapheme-aware.
This is important for emoji too.
Truncation
Do not cut a string at arbitrary byte length.
You can break:
- UTF-8;
- combining sequence.
Use Unicode-aware truncation and preferably word/line layout.
Subtitles
Subtitle line breaking must be target-language aware.
CJK and RTL need player-specific testing.
PDF/DOCX
After translation:
- visual compare.
Fixed layout can clip target typography.
Quality checks
Automate:
- Unicode validity;
- target script;
- broken placeholders;
- invalid tags;
- double spaces where inappropriate;
- forbidden ASCII substitutions.
Human checks:
- typography;
- natural punctuation.
Locale-aware punctuation in style guides
Create target-language examples for:
- quotations;
- nested quotations;
- dialogue dashes;
- list punctuation;
- abbreviations;
- units.
A general instruction such as “preserve punctuation” is misleading. Preserve the syntactic function, then use target conventions.
Unicode Normalization Form C
Many text systems use NFC as a practical normalization form because it composes characters where canonical composed forms exist. The exact policy should be documented and applied consistently across:
- source ingestion;
- glossary matching;
- QA;
- search.
Do not repeatedly normalize in different ways at every layer.
Grapheme-aware UI testing
A visually perceived character may consist of several code points. Use Unicode grapheme segmentation when:
- counting visible characters;
- cursor movement;
- deleting/backspacing;
- truncating.
Code-point count and byte count are poor proxies for user-visible length.
Line breaking and CJK kinsoku-style constraints
East Asian typography has conventions around punctuation that should not begin or end lines in inappropriate positions. Unicode line-break classes provide default behavior, while language-specific typography may require additional tailoring.
Use mature layout engines instead of manual line wrapping.
Thai and languages without ordinary word spaces
A simple split(" ") cannot determine words or line-break opportunities reliably. Search, truncation and subtitle tools should use language-aware segmentation.
This is a software internationalization requirement, not a translation problem.
Formatting placeholders
A localization string may contain:
<strong>{count}</strong> items
The target can reorder the words, but the tag and variable must remain structurally valid.
Use parsers rather than regex-only translation of markup-heavy content.
Bidirectional punctuation
In mixed Arabic/English text, neutral punctuation can visually attach to the wrong run if direction isolation is missing. Test punctuation around:
- parentheses;
- colons;
- slash;
- URLs.
This is governed by bidi context, not merely the character shape.
Font metrics and text expansion
Two fonts supporting the same script can have very different widths and line heights. A localization QA pass should use the real production font stack.
Do not approve layout with a fallback font that will not ship.
File conversion risks
Converting:
- DOCX → PDF;
- HTML → PDF;
- PPTX → PDF
can alter line breaks and font fallback. Validate the final exported artifact separately from the editable source.
Final principle
Multilingual formatting quality comes from respecting Unicode and target typography at every layer, from string storage to line breaking to final rendering. Correct translation text is only the beginning.
Vertical text and other writing directions
Not all multilingual layout is horizontal LTR or RTL. East Asian publishing can use vertical text in specialized contexts. Unicode has standards work for vertical text layout, and CSS supports vertical writing modes.
Most web/business content remains horizontal, but a document or publishing project should not assume horizontal layout is universal.
Unicode text segmentation
Unicode Standard Annex #29 defines grapheme, word and sentence boundaries. These boundaries are useful for:
- cursor movement;
- text selection;
- word counting;
- sentence segmentation.
A translation or UI system built on ASCII whitespace rules can fail badly on scripts that use combining marks or different segmentation conventions.
Normalization and security
Unicode normalization should be deliberate. Over-normalizing can change distinctions in some contexts, while failing to normalize can cause:
- duplicate glossary misses;
- search mismatch.
Security-sensitive systems also need to consider visually confusable characters across scripts.
Confusable characters
Latin a, Cyrillic а and other glyphs can look similar but are distinct code points. A translated identifier should not silently mix scripts because:
- search;
- authentication;
- audit
may treat them differently.
Run script-consistency checks on identifiers and high-risk names.
Punctuation around variables
Dynamic localization strings frequently place punctuation near variables:
Hello, {name}!
A target language may move or remove the comma/exclamation. Keep punctuation outside the protected variable while allowing the sentence to restructure.
Do not treat the entire source string as a template that must retain exact punctuation positions.
Nonbreaking typography
Some locales conventionally keep:
- number + unit;
- initials + surname;
- punctuation combinations
on one line. Use nonbreaking spaces or appropriate layout rules when required.
Avoid inserting plain ASCII spaces that allow awkward line breaks.
Spreadsheet and CSV formatting
A CSV delimiter may be comma while local numeric formatting also uses comma decimals. CSV is a machine data format; do not localize the delimiter automatically unless the receiving system specification changes.
Separate file syntax from display formatting.
Markdown and documentation pipelines
Markdown can contain:
- tables;
- code;
- links;
- inline emphasis.
Translate prose while preserving syntax. Run a Markdown parser/renderer after translation to catch broken pipes, brackets or code fences.
Source-code comments
Comments in code may be translatable, but do not translate:
- identifiers;
- string keys;
- syntax.
Localization and code translation are different tasks.
Testing fonts before launch
Build a glyph coverage test containing:
- all target alphabets;
- punctuation;
- common symbols;
- diacritics.
Render it with the production font stack. Missing glyphs should be found before real content arrives.
Multilingual typography review
Native reviewers can flag target-language punctuation, but a typographer or localization QA specialist may need to handle:
- line breaks;
- font selection;
- vertical alignment.
Complex writing systems benefit from both linguistic and visual expertise.
Final engineering principle
Store semantic text cleanly and let standards-compliant layout engines determine how it is shaped and wrapped. The more formatting logic is embedded inside translated strings, the harder the system becomes to maintain across scripts.
Implementation takeaway
For production use, treat Unicode segmentation, grapheme safety, target typography and final-render QA as measurable parts of the workflow rather than assumptions. Define the relevant policy before processing content, keep the model or data configuration versioned, and verify results on representative material from the actual language, locale and domain. If automation produces a result that conflicts with a deterministic rule, authoritative terminology or qualified human evidence, escalate the item instead of averaging the disagreement away. The most durable multilingual systems preserve source-to-target traceability, record exceptions and feed reviewed corrections back into benchmarks, glossaries or routing rules. That discipline makes quality improvements reproducible when models, providers, reviewers or source content change.
Frequently asked questions
Should punctuation be translated?
Punctuation should follow target-language conventions while preserving sentence meaning/structure.
What is Unicode normalization?
A process that converts equivalent character sequences into consistent representations.
Why is English line wrapping unsafe for other scripts?
Other scripts have different word and line break rules.
Can I replace all punctuation with ASCII?
No. That can damage correct target typography and orthography.
What standards matter?
Unicode UAX #14 for line breaking, UAX #9 for bidi, and CLDR for locale formatting.
Conclusion
Multilingual formatting succeeds when content structure and target typography are handled separately.
Preserve semantic markup, use Unicode correctly, localize punctuation and number conventions and let internationalized rendering engines handle script behavior.
A translation is not complete until the target writing system renders naturally and reliably in the actual product.
Research references
- Unicode UAX #14 Line Breaking:
- Unicode UAX #9 Bidirectional Algorithm:
- Unicode Standard:
- CLDR number symbols:
- W3C Internationalization: