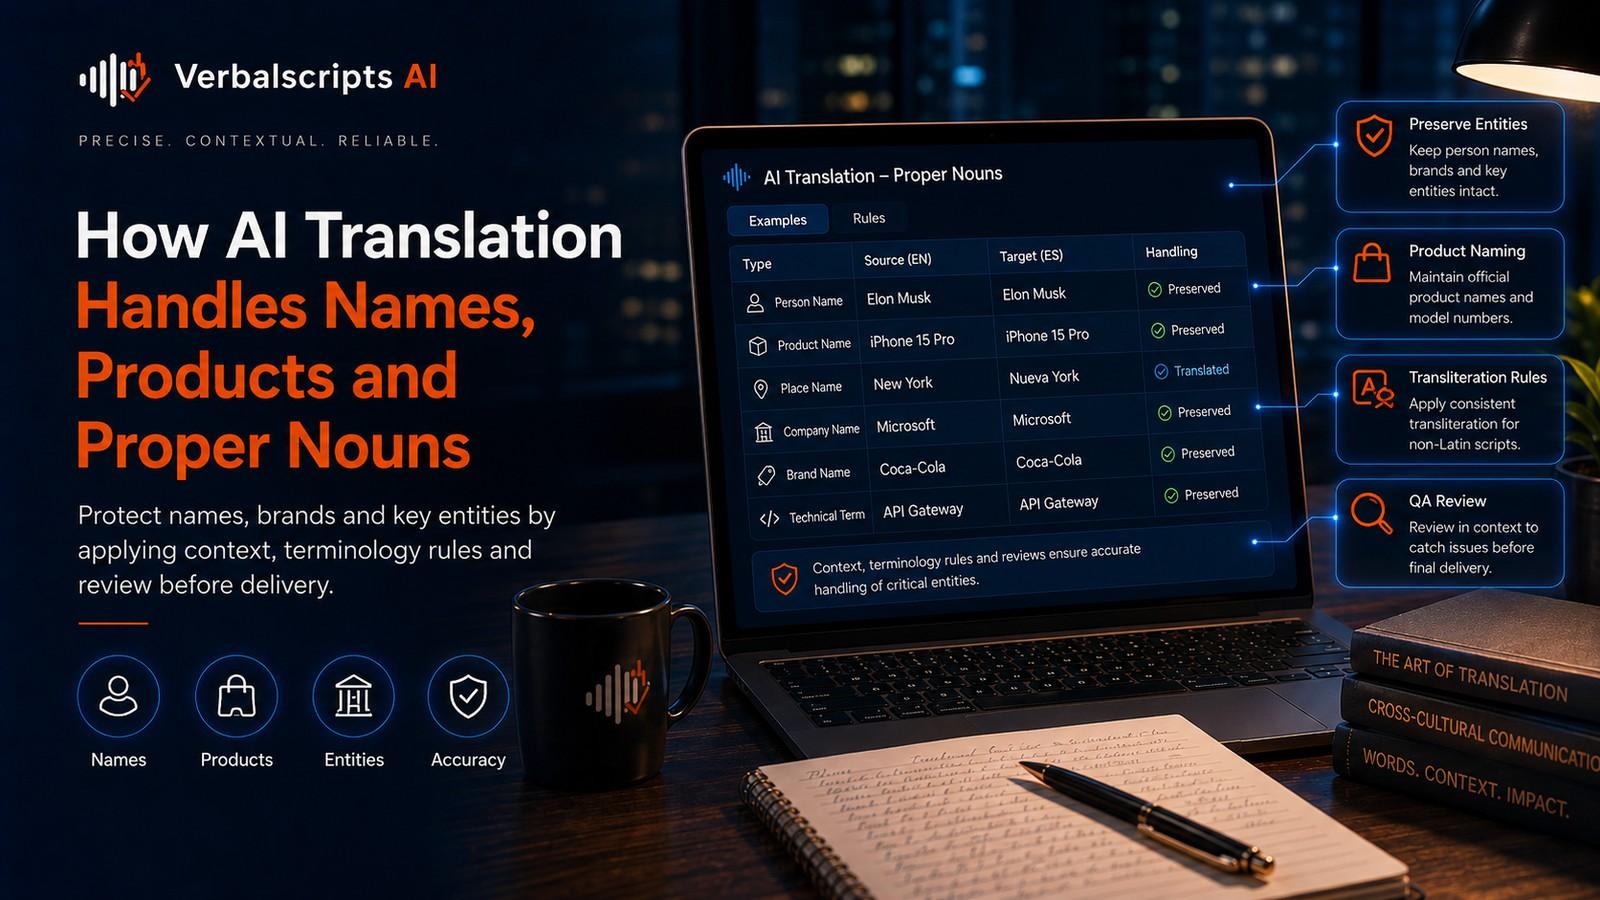
How does AI translation handle names and product names? A modern system usually identifies a proper noun from context, then chooses among preservation, transliteration, conventional translation or glossary-controlled substitution. The correct strategy depends on the entity, target script, locale and client rules. For important names, approved terminology and human verification are safer than relying on automatic inference alone.
Names look simple until they cross languages. A person’s name may need to be preserved exactly, transliterated into another script or rendered according to an established local convention. A product name may need to remain in English even while the surrounding text is translated. A city may have a conventional translated name that differs substantially from its source-language form.
For production multilingual workflows, see our AI Translation service for the delivery path behind the guidance in this article.
That makes names and proper nouns a distinct quality-control problem in AI translation.
The core principle is simple: a name should be handled according to the identity it represents, not only according to the letters it contains.
What counts as a proper noun in translation?
Proper nouns include more than personal names. Common categories are:
- people;
- companies;
- product and feature names;
- organizations;
- government bodies;
- places;
- institutions;
- book, film and media titles;
- events;
- laws and treaties;
- trademarks;
- model numbers and identifiers.
Each category can require different behavior.
“New York” has established forms in many languages. A newly launched software feature may have no translated name at all. A personal name written in Arabic, Cyrillic, Chinese or another script may require transliteration when used in a Latin-script document.
Four main strategies
AI translation systems generally need to choose among four actions.
Preserve
Keep the source form unchanged.
This is common for trademarks, model numbers, usernames, URLs, many product names and some personal names.
Transliterate
Represent the pronunciation or written form of a name in another script.
For example, a Cyrillic name may be rendered in Latin letters. Transliteration is not translation: it changes script rather than semantic meaning.
Translate
Use a conventional target-language name or translated title.
Countries, international organizations, historical figures and famous works may have established translated forms.
Substitute an approved form
Use a client- or institution-approved target version from a glossary, database or identity record.
For enterprise workflows, this is often the safest method because it removes guesswork.
Why names are difficult for AI
Names are highly ambiguous. Ordinary words can also be names. “Apple” can refer to fruit or a company. “Jordan” can be a country, a person or a brand reference. “May” can be a month, a modal verb or a surname.
Context helps, but context can be incomplete.
Names also vary in morphology. In some languages, personal and place names take case endings or grammatical inflections. A model that preserves the source form mechanically may create an ungrammatical sentence. A model that changes the name too freely may corrupt identity.
The challenge becomes larger across scripts because the system has to decide not only what the entity is but how it should be represented.
Transliteration is not one universal mapping
There is no single transliteration scheme that satisfies every use case. Academic systems, passports, libraries, governments and news organizations may use different conventions.
A person may already have an official Romanized spelling that differs from what an automatic transliterator would produce. That official spelling should usually take priority.
This is why identity-sensitive content should use authoritative reference data where available:
- passport spelling;
- corporate registry;
- official website;
- trademark database;
- client-provided list;
- publication style guide.
AI is useful for proposing a transliteration, but it should not overwrite an established form without reason.
Named entity recognition and translation
A translation pipeline often benefits from identifying entities before translating them.
Conceptually, the process is:
- detect a probable entity;
- classify it as person, organization, location, product or other type;
- look for a glossary or approved form;
- determine whether it should be preserved, translated or transliterated;
- apply grammatical changes only where appropriate;
- verify consistency across the document.
Research on named-entity transliteration has treated the task as a sequence-to-sequence problem similar to neural machine translation. Work such as Grundkiewicz and Heafield’s NEWS 2018 study shows how transliteration can be modeled directly, but production workflows still need business rules because a technically plausible transliteration may not be the officially preferred spelling.
Product names and trademarks
Product names should not automatically be translated. A translated product name can create several problems:
- users cannot find the product;
- the wording may conflict with trademark policy;
- documentation becomes inconsistent;
- search queries fail to match;
- support teams use different labels;
- the translated name may accidentally describe a different product.
A terminology glossary should therefore mark each product name with an explicit rule:
Do not translate, use approved localized name, or translate descriptor only.
For example, a product family may remain in English while a descriptive phrase around it is localized.
Google Cloud’s translation documentation explicitly notes that glossaries can be used both to enforce specific translations and to prevent product names or borrowed words from being translated. That is a useful model for enterprise translation design generally.
Personal names
Personal names require special care because an error is not merely stylistic. It can affect identity.
A robust workflow should preserve:
- spelling;
- order;
- initials;
- titles;
- diacritics;
- hyphenation;
- generational suffixes;
- official transliteration when known.
Name order also differs between cultures. Some languages commonly place the family name first. Translation systems should not reorder names unless the target style or dataset explicitly requires it.
When a document is legal, immigration-related, financial, academic or medical, compare the translated name against the authoritative source field rather than relying on a generated form.
Place names
Places often have established exonyms: target-language names that differ from the local endonym. The best form depends on audience and publication policy.
A general news article might use the conventional English name familiar to readers. A mapping product may prefer official local naming. A legal document may need the spelling from a government record.
Geographic names can also be politically sensitive. The translation workflow should therefore distinguish linguistic convention from policy decisions and use a defined source of truth.
Company and organization names
Organizations may have:
- one official name used globally;
- an officially translated name;
- multiple historical names;
- a legal entity name plus a consumer brand;
- an acronym that differs by language.
Do not assume the company name should be translated because its individual words are translatable. Verify whether an official localized name exists.
The same applies to government departments and international organizations. Established translations should take priority over ad hoc model output.
Titles of books, films and creative works
Creative titles may have official localized versions that are not literal translations. When the work has already been distributed in the target market, the official local title is usually the best choice.
If no official version exists, the purpose matters. A bibliography may preserve the original title and add a translation in brackets. Marketing copy may need a more natural localized title. Academic discussion may require both.
Acronyms and abbreviations
Acronyms create a related problem. Some remain unchanged internationally; others are translated; others use a different acronym in the target language.
A glossary should record both full forms and abbreviations. It should also specify whether the first mention should be expanded.
For example:
| Source | Target rule |
|---|---|
| Product X | Do not translate |
| Example Agency (EA) | Use official localized name and target acronym |
| API | Keep “API” |
| Internal team nickname | Translate only if context requires |
Cross-script search and discoverability
Names influence search. If a user searches for a Latin-script product name, a page that contains only a transliterated local-script form may be harder to find. In some contexts, using both forms is useful.
For example, an article may introduce a name as:
Local-script form (Latin transliteration)
or the reverse, depending on the audience.
Search optimization should not override readability, but multilingual SEO teams should decide how named entities will appear in titles, body text, alt text and metadata.
Non-Latin scripts and Unicode
Proper noun handling is also a text-engineering issue. Different scripts may contain visually similar characters that are not the same Unicode code point. Copying names between systems can also introduce normalization differences.
Production pipelines should preserve Unicode cleanly and avoid replacing characters with approximate ASCII equivalents unless a downstream system requires it.
When content mixes right-to-left and left-to-right scripts, names, numbers and punctuation can also display in unexpected order. Unicode’s Bidirectional Algorithm and W3C guidance are relevant for rendering, even though translation quality and rendering quality are separate concerns.
A recommended workflow for names
Step 1: Extract named entities
Identify people, organizations, products, locations and titles before or during translation.
Step 2: Match against approved data
Check the project glossary, client database or official source.
Step 3: Assign a handling rule
Preserve, transliterate, translate or use approved form.
Step 4: Translate in context
Do not isolate the entity from grammar completely; surrounding inflections and particles may depend on it.
Step 5: Run consistency checks
Search for variant spellings and unintended translations.
Step 6: Perform human verification
Verify high-impact names, especially in legal, financial, medical, public-facing and identity-related content.
Quality checks for proper nouns
A dedicated name QA pass can catch errors that general proofreading misses.
Check:
- exact spelling;
- capitalization;
- diacritics;
- script;
- official local form;
- repeated consistency;
- title and honorific;
- grammatical inflection;
- acronym;
- model number;
- trademark symbol if required;
- search-friendly first mention.
Automated detection can flag inconsistencies, but a reviewer needs to know which form is authoritative.
Common AI errors
Translating a brand literally
This can produce a semantically sensible but commercially incorrect name.
Inconsistent transliteration
The same name appears with two Latin spellings in different sections.
Mistaking a common noun for a name
Capitalization or context may trigger false entity detection.
Mistaking a name for an ordinary word
The model translates a surname or product name because it resembles a common word.
Inventing an official local name
A plausible translation is generated even though no official localized name exists.
Dropping diacritics
This may change pronunciation or identity and should not be treated as harmless formatting.
When human review is essential
Human verification is especially important for:
- court and legal documents;
- passports and immigration material;
- medical records;
- academic certificates;
- contracts;
- financial compliance;
- public statements;
- high-profile marketing;
- datasets used for entity linking or search.
For low-risk internal content, automated handling may be sufficient if the system can enforce a strong glossary.
Frequently asked questions
Should personal names be translated?
Usually no. They are normally preserved or transliterated. Established historical or conventional target-language forms are exceptions.
What is the difference between translation and transliteration?
Translation changes meaning from one language to another. Transliteration changes the writing system used to represent a word or name, usually aiming to preserve pronunciation or orthographic correspondence.
Should product names be translated?
Only when an approved localized product name exists or the brand’s naming policy explicitly requires translation. Otherwise they should normally remain unchanged.
Can AI transliterate names accurately?
Often, but there may be multiple valid systems and an official spelling may differ from the model’s choice. Identity-sensitive uses should be verified.
How do glossaries help with names?
A glossary can specify approved target forms and mark terms that must not be translated, reducing inconsistency across large multilingual projects.
Conclusion
Names, brands and proper nouns are a small share of most documents but a disproportionate source of visible translation errors. Their correct treatment depends on entity recognition, language knowledge, script handling, authoritative reference data and project rules.
The best AI translation workflow does not ask the model to guess every name from scratch. It combines AI context with controlled terminology and human verification where identity or brand consistency matters. That approach protects both linguistic quality and the entities the text is actually talking about.
Research references
- Grundkiewicz & Heafield (NEWS 2018), *Neural Machine Translation Techniques for Named Entity Transliteration*:
- Google Cloud, *Overview of the Cloud Translation API* (glossary behavior):
- Unicode Consortium, *Unicode Bidirectional Algorithm*:
- W3C, *Language tags in HTML and XML*: