For language operations leaders, QA managers, reviewers, localization teams and enterprise buyers, human-in-the-loop AI translation sits between raw human communication and a downstream decision. That makes it a systems problem as much as a language problem. Model quality matters, but so do recording conditions, instructions, metadata, review, security, formatting and the way errors are measured.
The central problem is defining what “good enough” means. Review without a shared rubric becomes subjective, while a single automatic score can miss critical errors. In human-in-the-loop AI translation, the rubric should explicitly cover machine output plus bilingual post-editing, as well as accuracy and completeness, along with severity and escalation.
Quick answer
Human-in-the-Loop AI Translation works best when teams define the intended use first, provide representative data and context, measure the specific errors that matter, and route uncertain or high-risk output to qualified human review. The best system is not the one with the strongest generic benchmark; it is the one whose measured behavior matches the deployment conditions and acceptance criteria.
What Human-in-the-Loop AI Translation means in practice
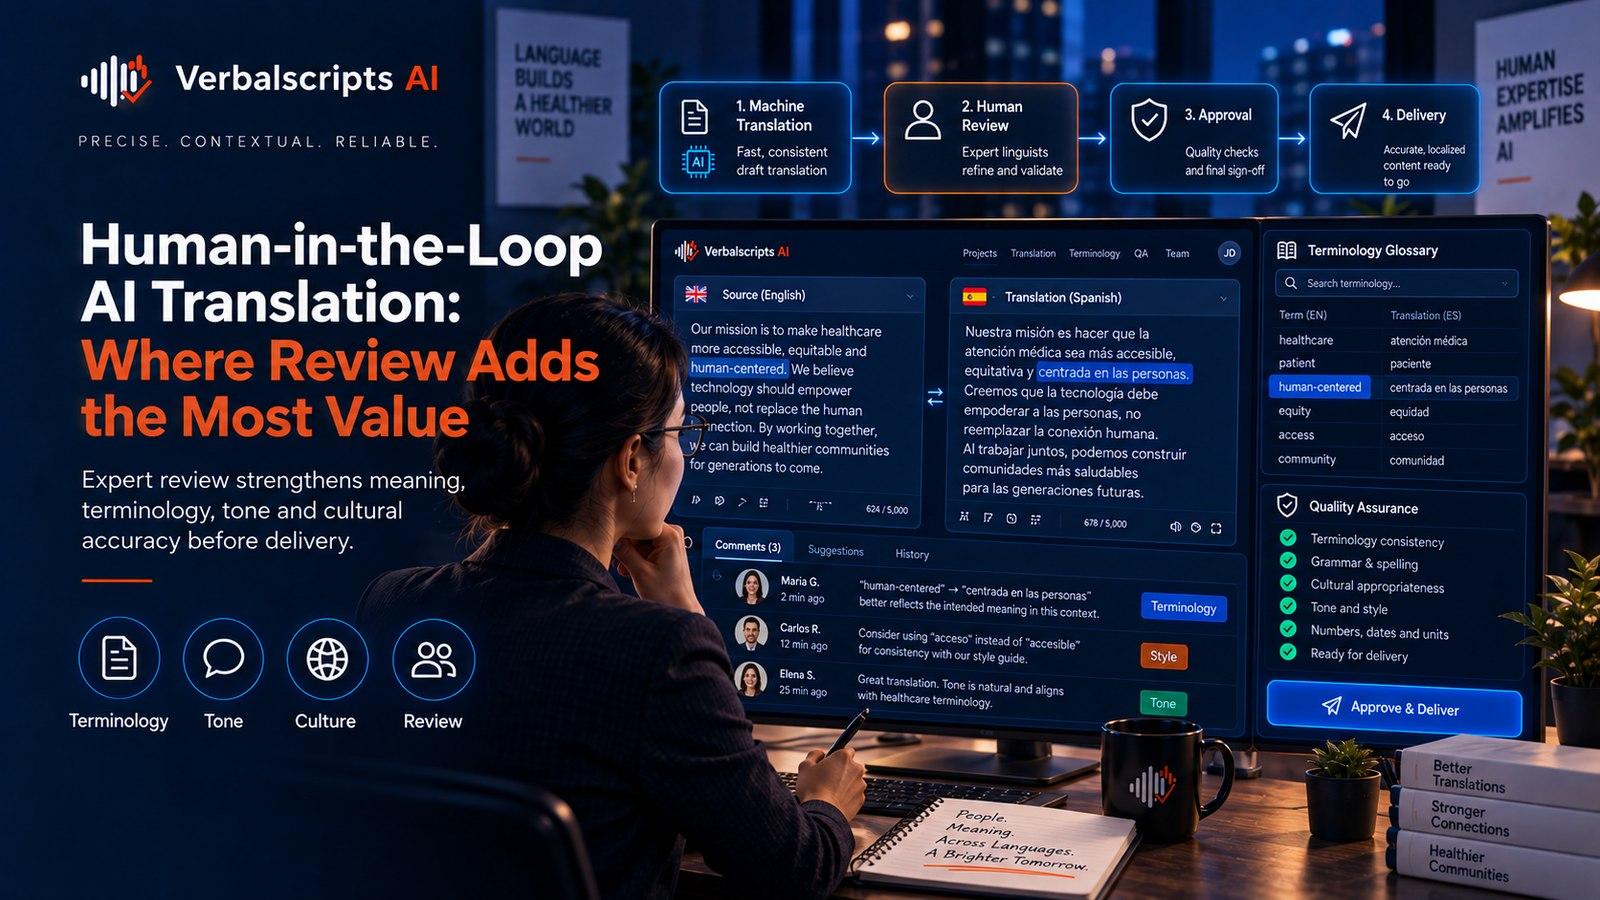
The review process for human-in-the-loop AI translation is best understood as controlled verification. The reviewer is not simply “making the text nicer.” The reviewer compares output with a source of truth, applies a style or quality specification, records material errors and resolves uncertainty at the appropriate level of expertise. In this workflow, one requirement the reviewer must be able to verify is machine output plus bilingual post-editing.
The distinction among proofreading, editing, source verification and domain review matters in human-in-the-loop AI translation because those activities have different scopes. If a team labels all of them “QA,” it becomes impossible to estimate effort or interpret a pass rate. Define the review operation at project level, train reviewers against concrete examples, and include accuracy and completeness in calibration material.
Why the hard cases matter
MQM separates translation quality into dimensions including terminology, accuracy, linguistic conventions, style, locale conventions, audience appropriateness, and design/markup. This helps teams avoid treating “quality” as a single vague impression.
The practical edge cases in human-in-the-loop AI translation are predictable, but they are not all equally important. Start with two priority areas (machine output plus bilingual post-editing; and accuracy and completeness) then add cases where context is sparse, the source is noisy or ambiguous, or an automated result triggers a downstream action. Instead of averaging those failures away, make them explicit in the test plan and assign an owner for each exception path.
The quality dimensions to design for
1. Machine output plus bilingual post-editing
Treat machine output plus bilingual post-editing as a design decision within human-in-the-loop AI translation. Write the requirement in operational terms, attach positive and negative examples, and test it on representative content before scaling. Record not only whether an output passed but why it failed, because recurring error categories are more actionable than one average score. Where the requirement is high risk, add a second source of evidence such as human review, a reference list or a targeted validation rule.
2. Accuracy and completeness
Tie accuracy and completeness to the downstream purpose of human-in-the-loop AI translation. “Accurate” should mean more than a single percentage: specify which wording, speakers, entities, numeric values and structural elements must be correct, and which errors trigger rework. A research quotation, call-center intent field and training-data label can tolerate different error profiles. The acceptance rule should therefore be written from the consequence of error backward, then tested on representative material.
3. Terminology and style
Use terminology and style as targeted context in human-in-the-loop AI translation, where rare but important vocabulary can create outsized errors. Names, product terms, acronyms and specialist vocabulary may be rare in general model training data even though they are common in one organization. Supply authoritative spellings and approved equivalents before processing, and preserve the source reference used to resolve a term. Track critical-term accuracy separately because one wrong drug, case name or product identifier may make an otherwise strong output unacceptable.
4. Locale appropriateness
Define locale appropriateness with language-specific rules for human-in-the-loop AI translation. Language tags alone do not capture locale, script, dialect, code-switching behavior or preferred terminology. Specify the target variety, decide how mixed-language phrases are represented, and keep source-language evidence available for review. For multilingual evaluation, report per-language results before aggregating; otherwise high-resource languages can mask weak performance in lower-volume markets.
5. Risk-tiered review
Convert risk-tiered review into observable criteria for human-in-the-loop AI translation. Define the error types reviewers will look for, which errors are critical, how samples are selected, and who adjudicates disagreements. A quality process is stronger when it records correction data rather than returning only “pass” or “fail.” Those corrections reveal whether the model, source material, instructions or reviewer guidance needs improvement and can become future benchmark examples.
A practical production workflow
Step 1: Write the quality specification
Define source of truth, error types, severity, style, critical terms, sampling and pass/fail thresholds before reviewers begin. For human-in-the-loop AI translation, this step should explicitly verify machine output plus bilingual post-editing. Record the decision in project metadata so later reviewers can reproduce the same rule.
Step 2: Create reviewer guidance and examples
Use positive and negative examples for ambiguous cases, speaker labels, terminology, omissions and formatting. For human-in-the-loop AI translation, this step should explicitly verify accuracy and completeness.
Step 3: Run the first review pass
Compare AI output with source material, record substantive corrections and tag uncertainty rather than silently guessing. For human-in-the-loop AI translation, this step should explicitly verify terminology and style.
Step 4: Escalate specialist decisions
Route legal, medical, technical, native-language or genuinely unclear cases to the appropriate expert or client reference. For human-in-the-loop AI translation, this step should explicitly verify locale appropriateness. Record the decision in project metadata so later reviewers can reproduce the same rule.
Step 5: Adjudicate and calibrate
Resolve disagreements, update anchor examples, and periodically test reviewers on the same controlled sample. For human-in-the-loop AI translation, this step should explicitly verify risk-tiered review.
Step 6: Measure residual quality
Sample released work, calculate agreed quality measures, analyze error categories and feed learning back into models, glossaries and guidelines. For human-in-the-loop AI translation, this step should explicitly verify feedback into glossaries and prompts.
How to evaluate quality
Measure human-in-the-loop AI translation with a rubric that distinguishes error type and severity. Translation teams can use an MQM-aligned subset; transcription teams can define equivalent categories for wording, speaker attribution, entities, timestamps and format. Review enough material to estimate the failure modes that matter rather than checking only easy samples.
Reviewer performance is part of the measurement system. Maintain a gold or adjudicated set, calculate agreement or accuracy on the same units, and investigate drift. A quality threshold is credible only when reviewers apply it consistently; the calibration sample should include machine output plus bilingual post-editing and accuracy and completeness.
- Measure or review machine output plus bilingual post-editing; define the unit, source of truth and pass/fail rule before scoring.
- Measure or review accuracy and completeness; define the unit, source of truth and pass/fail rule before scoring.
- Measure or review terminology and style; define the unit, source of truth and pass/fail rule before scoring.
- Measure or review locale appropriateness; define the unit, source of truth and pass/fail rule before scoring.
- Measure or review risk-tiered review; define the unit, source of truth and pass/fail rule before scoring.
Privacy, governance and operational controls
Human review in human-in-the-loop AI translation introduces another access path to sensitive content. Route only necessary files to reviewers, use role-based permissions, prevent uncontrolled downloads where appropriate, and define how reviewer workstations and subcontractors are governed. The reviewer should be able to retrieve source evidence for machine output plus bilingual post-editing without creating shadow copies of sensitive files.
Keep reviewer identity and decision logs for human-in-the-loop AI translation where accountability requires them, but avoid turning QA analytics into unnecessary surveillance. Measure the process (error categories, agreement, throughput and escalation) and use accuracy and completeness as a calibration target where relevant rather than collecting unrelated personal data about reviewers.
Common failure patterns
- Treating machine output plus bilingual post-editing as an informal preference instead of a testable requirement with examples and ownership.
- Treating accuracy and completeness as an informal preference instead of a testable requirement with examples and ownership.
- Relying on a general model for rare names and specialist terms even though authoritative reference spellings are available.
- Reporting a global multilingual average that hides weak performance in smaller languages or locales.
- Treating risk-tiered review as an informal preference instead of a testable requirement with examples and ownership.
A good corrective action for human-in-the-loop AI translation changes the system, not only the current file. If the failure involved machine output plus bilingual post-editing or accuracy and completeness, update the relevant guideline, reference data, validation rule, routing logic or evaluation set so the same class of error is easier to detect next time.
Implementation checklist
- ☐ Write the intended use, target users and unacceptable error types.
- ☐ Use representative inputs rather than only clean demonstration files.
- ☐ Define reviewer competence, error taxonomy, severity, sampling and escalation requirements.
- ☐ Choose automatic metrics and human review rules that match the deliverable.
- ☐ Document privacy, retention, access, consent or licensing obligations.
- ☐ Preserve version, provenance and source links needed for audit or correction.
Advanced implementation considerations
Design the benchmark before optimizing the system
It is tempting to tune human-in-the-loop AI translation against whatever data is easiest to obtain. That reverses the logic. First write the deployment population and failure costs, then build a benchmark that represents them. If the benchmark changes every time the model changes, improvement cannot be distinguished from a moving test. Keep one stable regression set and a separate challenge set for newly discovered edge cases.
Separate confidence from correctness
In human-in-the-loop AI translation, model confidence can help prioritize review, but confidence scores are not automatically calibrated probabilities of correctness. Validate how confidence relates to actual error on your data and on important slices. A high-confidence wrong name or speaker label can be more damaging than a low-confidence harmless filler. Use confidence for routing only after demonstrating that the thresholds behave predictably.
Track correction effort as a product metric
For human-in-the-loop AI translation, automatic scores describe output similarity; they do not directly describe the labor required to make a deliverable acceptable. Measure review minutes per audio minute, edits per thousand words, escalation rate, or another operational measure that fits the workflow. When two systems have similar accuracy, the one that produces easier-to-review structure can have substantially lower total cost.
Version instructions and reference data
In human-in-the-loop AI translation, prompts, style guides, glossaries, speaker rosters, annotation rules and normalization code are part of the effective model. Store their versions with the job or dataset. When quality shifts, operators should be able to tell whether the change came from the model, the input mix, the instructions, or human review behavior.
- ☐ Run a pilot, measure rework and exceptions, then scale only after the acceptance criteria are met.
Frequently asked questions
What is the goal of human-in-the-loop AI translation?
For human-in-the-loop AI translation, the goal is to produce evidence that output meets a defined specification, not merely to improve style. The reviewer should know the source of truth, error taxonomy and escalation rules.
Should every file receive full human review?
For human-in-the-loop AI translation, not always. Review depth can be risk-tiered, but the sampling policy and automatic gates should be validated against real residual error.
How do you prevent reviewer inconsistency?
For human-in-the-loop AI translation, use written rubrics, anchor examples, qualification tests, shared calibration samples and adjudication. Measure drift over time rather than assuming reviewer quality is static.
Can an LLM replace a reviewer?
For human-in-the-loop AI translation, it can assist with consistency checks and triage, but should be calibrated against human evidence. Audio-grounded or culturally ambiguous decisions still require access to the source and appropriate expertise.
What should happen to reviewer corrections?
For human-in-the-loop AI translation, store them as structured quality data where permitted. Error categories and approved corrections improve guidelines, glossaries, model prompts and future evaluation sets.
Scenario-based testing before scale
A useful final check for human-in-the-loop AI translation is to write three to five realistic failure scenarios before launch and force the workflow through them. Include at least one difficult but common input, one privacy or permission edge case, one quality disagreement, and one operational failure such as a retry, corrupt file or missing reference. For each scenario, define the expected state transition, who receives the exception, what evidence is preserved and what the user sees. This converts abstract requirements into observable system behavior.
For human-in-the-loop AI translation, scenario testing also reveals whether quality and operations are connected. A pipeline may detect low confidence correctly but still fail if there is no reviewer queue; a reviewer may resolve a name correctly but the corrected value may never reach the CRM or final export; a webhook may retry successfully but create a duplicate downstream record. Test the complete chain from source to accepted output and record the result as part of release readiness.
Conclusion
Human-in-the-Loop AI Translation: Where Review Adds the Most Value is most useful when it is treated as a measurable workflow rather than a feature checkbox. Define the source of truth, preserve the context that the next step needs, test the hard cases, and make review depth proportional to risk. The result is faster automation without sacrificing traceability or quality discipline. For Verbalscripts AI, the practical objective is a language-data pipeline that can move from AI speed to human-reviewed reliability when the project requires it, while keeping output structured enough for research, product and enterprise systems.
Research references
- ISO 5060:2024 (Translation services) Evaluation of translation output: https://www.iso.org/standard/80701.html
- ISO 18587:2017 (Post-editing of machine translation output) Requirements: https://www.iso.org/standard/62970.html
- ISO 17100:2015 (Translation services) Requirements for translation services: https://www.iso.org/standard/59149.html
- MQM Council, The MQM Error Typology: https://www.themqm.org/mqm-pillars/typology/
- MQM Council, The MQM Scoring Models: https://www.themqm.org/mqm-pillars/the-mqm-scoring-models/
- NIST AI Risk Management Framework 1.0: https://www.nist.gov/itl/ai-risk-management-framework