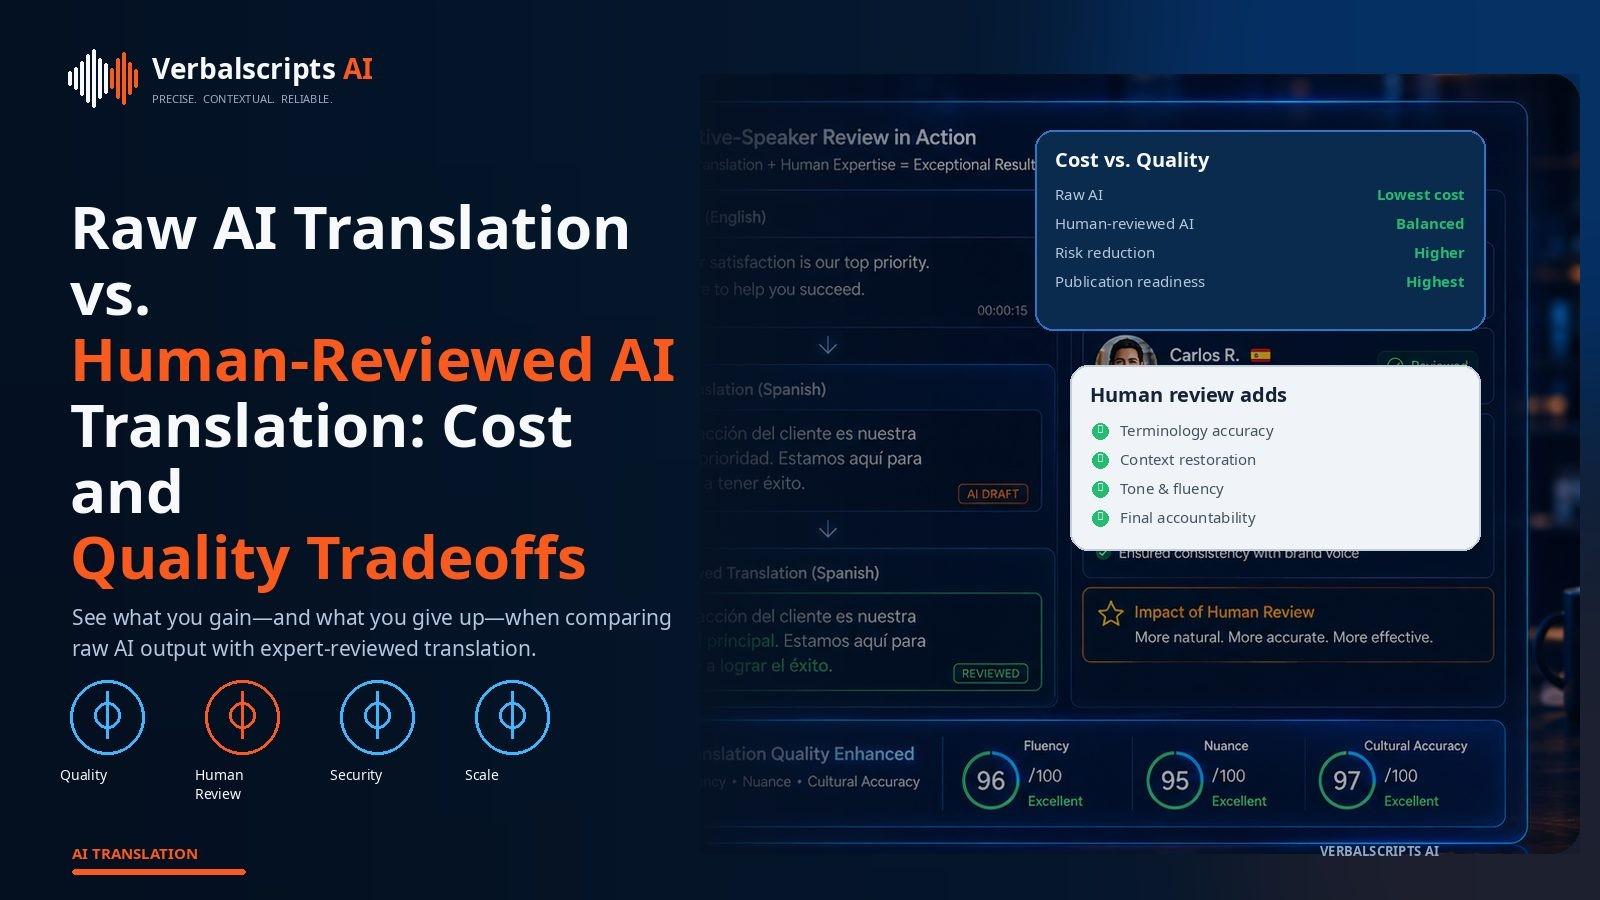
The real cost of AI language services is not the API sticker price alone. Buyers should model billable units, feature add-ons, storage and egress, integration, quality failures, reprocessing, human review, project management, security requirements and support. The cheapest raw rate can become the most expensive workflow if accuracy or operational fit is poor.
Key takeaways
Key Takeaways
- Define quality and acceptance criteria before selecting a model or vendor.
- Evaluate on representative material and report slice-level results, not just one average score.
- Use human review selectively where confidence is low or the consequence of an error is high.
- Capture errors and corrections in structured form so the workflow improves over time.
- Optimize total cost per accepted output, not only raw API or model consumption.
Why This Topic Matters Now
As speech recognition, translation and multimodal language models converge, the main enterprise differentiator is shifting from access to a model toward the surrounding data, evaluation, governance and human-expertise system. “State of Human-Reviewed AI language services: Quality, Cost and Buyer Expectations” is best read through that lens rather than as a prediction that automation eliminates quality operations.
This guide translates that problem into concrete design and evaluation choices. It defines what to specify before implementation, what to measure, how to test difficult cases, where human review adds value, and which security or procurement questions should be answered before the workflow is scaled. The objective is a system that can be audited and improved, not a marketing claim that depends on ideal inputs.
The Core Technical and Operational Issues
Normalize units before comparing price sheets. Speech APIs may bill per second/minute/hour; translation systems may bill source characters, tokens, pages or subscription capacity. Convert them to your actual monthly workload and include target-language multiplication.
As of September 2026, Google Cloud publishes standard Speech-to-Text V2 pricing starting at $0.016 per processed minute for the first 500,000 monthly minutes, with dynamic batch listed at $0.003 per minute. Those numbers illustrate why raw inference can be cheap relative to review, integration and error handling; verify live pricing before publication or procurement.
For public research content, publish the methodology and limitations as prominently as the headline result. Record model versions and test dates because hosted AI services can change. Avoid comparing scores taken from different vendors’ marketing pages as though they came from one controlled experiment.
Recent vendor announcements illustrate the pace of change: Microsoft reported in September 2026 that MAI-Transcribe-2 achieved 5.2% average WER on FLEURS across 60 languages, while Deepgram describes Nova-3 as supporting real-time multilingual transcription and vocabulary adaptation. These are vendor-reported claims, not independently reproduced Verbalscripts AI results, and they should be treated as signals to test, not conclusions to copy.
A Practical Enterprise Scenario
Consider an enterprise processing 100,000 units of AI language services each month. Vendor A has the lower raw price but requires twice the human review and more engineering to handle failures; Vendor B costs more per unit but delivers cleaner structured output and stronger operational controls. A TCO model can make Vendor B cheaper even when its price sheet looks worse.
Methodology: What Can Be Claimed Defensibly
A credible benchmark begins with a public methodology before results are calculated. Define the systems and versions, dates tested, source dataset, inclusion rules, languages and domains, hardware or API settings, normalization, prompt or glossary configuration, reference creation, metric formulas and confidence intervals. Freeze inputs before testing and do not tune each system differently unless the benchmark explicitly studies best-case customization.
Report both aggregate and slice-level results. Include distributions, sample sizes, critical errors and examples of failure modes. For vendor-hosted systems, record the test date because models can change behind an API name. If one vendor publishes its own benchmark claim, label it as vendor-reported and avoid blending it into an independent league table without reproducing the test.
For Verbalscripts AI, a defensible research article should not invent proprietary benchmark scores. Until a controlled experiment is executed, the article can explain methodology, cite public research or vendor-reported findings with clear attribution, and publish the test design that future measured results will follow. That preserves trust and creates a stronger foundation for original research later.
What the 2026 Evidence Already Shows
The important 2026-to-2027 trend is convergence. Speech systems are adding multilingual recognition, diarization, timestamps, vocabulary adaptation and richer formatting, while translation systems increasingly combine neural MT, large language models, terminology control and document context. Multimodal research such as Meta’s Seamless family demonstrates a direction in which speech recognition and speech translation are less rigidly separated.
At the same time, benchmark claims need more scrutiny, not less. Vendor announcements may report strong results on public datasets or proprietary tests, but the numbers are not automatically comparable when normalization, language mix, audio conditions, latency or model configuration differs. Enterprise teams are therefore moving toward private, representative evaluation sets and continuous regression testing rather than selecting a model from a public leaderboard alone.
Human expertise is becoming more targeted. Reviewers are increasingly used for gold-set creation, difficult language/domain slices, terminology, adjudication, safety and high-consequence output rather than manually processing every easy item. The durable competitive advantage is likely to be the quality of the data, evaluation and workflow around models, not simply access to a model that competitors can also license.
Evaluation Metrics and Failure Analysis
Quality for AI language services must be defined before it can be improved. Establish a reference standard, scoring rules and sampling plan, then separate model errors from workflow errors. The reference itself needs quality control: inconsistent human labels create an evaluation ceiling and can make a better system appear worse.
Choose metrics that reflect the downstream task, and report distributions and worst slices rather than only averages. A dataset or workflow that is excellent on the dominant slice may still fail the users who matter most.
Track severity as well as frequency. A missing comma and a wrong medication name should not carry the same business weight; neither should a stylistic translation choice and an omission that changes meaning. A practical program uses a critical-error taxonomy and defines which errors trigger rejection, mandatory review, customer notification or retraining.
Never stop at an overall average. Build evaluation slices that reflect the variables likely to change performance: locale, accent or dialect, domain, recording device, channel, background noise, speaker count, overlap, utterance length, document format, terminology density and content risk. Report the sample size for every slice so a dramatic percentage is not mistaken for a robust result when it comes from only a handful of items.
Set launch gates on the slices that matter most. A release can improve the global score while becoming worse on one language or one high-value customer domain. Regression policy should specify which failures block release, which trigger targeted human review, and which can ship with a documented limitation. This turns evaluation from a retrospective report into an engineering control.
Data, Language Coverage and Representation
High-quality AI language services data is purpose-specific. Start from the intended model behavior and work backward to the examples, labels and metadata needed to learn or test that behavior. Define inclusion and exclusion rules before collection begins; otherwise the dataset accumulates whatever is easiest to acquire rather than what the model needs.
Measure coverage across the conditions the target model will see: languages/locales, accents, devices, acoustic environments, speaker demographics where lawful and appropriate, domains, utterance length and rare phenomena. “More hours” is not synonymous with “more coverage.”
Quality control should combine automated validation and human review. Automated checks can catch missing fields, invalid timestamps, impossible durations, duplicate files, label-schema violations, language mismatches and train/test overlap. Human review is needed for semantic correctness, boundary judgment, speaker attribution, nuanced language and culturally specific issues. Track reviewer agreement and adjudication rates as signals of guideline quality.
Document the dataset like a product. A useful datasheet or dataset card describes motivation, composition, collection, preprocessing, annotation, known limitations, licensing, intended uses, out-of-scope uses and maintenance. That documentation makes later procurement and model-governance decisions much safer.
Create train, validation and test splits at the correct unit. In speech, splitting random clips from the same speaker across train and test can inflate performance because the model has effectively seen the voice before. In document translation, near-duplicate sentences, template boilerplate or versions of the same document can leak across splits. Group by speaker, conversation, source document or collection episode where appropriate.
Deduplicate both exact and near-duplicate content before finalizing the splits. Preserve a frozen test set that is never used for tuning prompts, choosing checkpoints or adjusting annotation guidelines after seeing results. When the production distribution changes, add a new evaluation slice rather than silently replacing the historical test set; that preserves comparability over time.
Human Review as an Evaluation and Control Layer
Human review should be risk-based rather than all-or-nothing. Route cases using confidence, domain, language, customer requirements and the potential cost of an error. High-confidence, low-risk material may pass automatically after sampling; low-confidence or high-consequence material should receive full review. Sampling should also include apparently easy cases so silent regressions are not missed.
Review instructions need examples, not only principles. Define how to handle names, numbers, abbreviations, speaker identity, inaudible content, code-switching, terminology, omissions, additions, formatting and ambiguous source material. Calibrate reviewers on a shared set, compare disagreement, adjudicate recurring edge cases and update the guideline. Human review becomes more consistent when reviewers are measuring the same definition of “correct.”
Capture corrections structurally. Store the original model output, corrected output, error category, severity and context where permitted. That turns review from a cost center into evaluation and improvement data, while maintaining a clear audit trail of what changed and by whom.
Security, Governance and Enterprise Adoption
Security should be mapped to the data lifecycle, not added only at upload. Use TLS for data in transit and strong encryption for stored source files, intermediate artifacts, outputs and backups. Centralize identity, require multi-factor authentication for privileged access, implement least privilege and role separation, and use short-lived credentials or signed URLs for automated retrieval. Secrets should be managed outside code and rotated through a defined process.
Logging must support accountability without becoming a second copy of sensitive content. Record who accessed what, when, from which service or role, and what action occurred; avoid writing transcript text, document content, access tokens or unnecessary PII into operational logs. Protect logs from modification or unauthorized deletion and define retention based on investigation and compliance needs. NIST CSF 2.0 places governance alongside identify, protect, detect, respond and recover, which is a useful reminder that controls require ownership and ongoing review, not just technology.
Vendor security reviews should examine subprocessors, data locations, breach-notification commitments, vulnerability management, penetration testing, key management, backup practices, personnel access, secure development and evidence such as independent assurance reports. Certifications can reduce due-diligence effort, but they do not prove that a particular workflow is configured safely.
2027 Outlook and Research Questions
Because this article is being prepared in September 2026 for a 2027 content program, statements about 2027 should be framed as an outlook unless they are later refreshed with measured 2027 data. The current evidence supports several likely themes: lower raw inference cost, stronger multilingual coverage, more integrated speech/translation capabilities, richer enterprise controls, and greater use of model routing and human review based on risk.
The harder problem will remain evaluation under real conditions. Accuracy gains on public benchmarks do not eliminate accent gaps, rare-entity errors, cross-talk, domain terminology, document-layout problems or translation omissions. Buyers will increasingly ask for evidence on their own content, plus auditable data handling and correction loops. That favors providers that can combine model choice with quality operations instead of selling one model as universally best.
How Organizations Should Prepare
Implement AI language services in phases. First, inventory the use cases and classify risk. Second, define inputs, outputs, quality and security requirements. Third, build a representative evaluation set and baseline the current workflow. Fourth, pilot the new workflow with controlled users. Fifth, automate observability, review routing and reporting. Sixth, expand languages, volume or use cases only after the previous phase is stable.
Assign owners across product/operations, engineering, security/privacy, language or domain quality, and procurement/legal. Most failures occur at the boundaries: a technically strong model is deployed without review guidance; a secure API feeds an insecure shared drive; a multilingual program has global tooling but no native-language QA ownership. Clear RACI and escalation rules are as important as the model configuration.
Implementation Checklist
- Document the use case, data sensitivity, languages/locales and downstream decision.
- Create a representative evaluation set and acceptance thresholds.
- Define the human-review routing rule and escalation path.
- Map data flows, subprocessors, retention, deletion and residency.
- Instrument quality, latency, cost, failures, review rate and critical errors.
- Pilot, record lessons, then scale in controlled stages.
Failure Modes to Test Before Production
Test AI language services against deliberate failure modes rather than only happy-path examples. Include corrupted or unsupported files, wrong language labels, empty segments, very long content, repeated uploads, partial network failure, duplicate webhook events, model timeouts and review exceptions where relevant. The system should fail visibly and recoverably instead of silently producing incomplete output.
Create a severity model for operational failures. A retryable timeout is different from a data-loss event; a low-confidence word is different from an unsupported file that appears to succeed. Dashboards should separate quality failures, infrastructure failures and policy failures so ownership is obvious.
Frequently Asked Questions
What should enterprises look for in AI language services?
Enterprises should evaluate AI language services against their own data, required languages, workflow, risk level and downstream use. The most important buying criteria are representative quality, operational fit, security, observability, human-review options and total cost, not a generic benchmark claim.
How should AI language services quality be measured?
Use a representative, human-verified test set and more than one metric. Combine an aggregate score with slice-level analysis and a critical-error taxonomy. For high-consequence speech or translation, include qualified human evaluation because a single automatic metric can hide errors in names, numbers, terminology, omissions or meaning.
When is human review necessary for AI language services?
Human review is most valuable when errors have meaningful consequences, the content is difficult or specialized, the language is low-resource, or the output will become a reference artifact. Risk-based routing is usually more efficient than reviewing every file or reviewing none.
What drives the real cost of AI language services?
Model effective cost per accepted output: API or platform charges plus human review, reprocessing, integration, storage, support and the expected cost of quality failures. Normalize vendor billing units before comparison.
Conclusion
The strongest approach to human-reviewed AI language services quality cost and buyer expectations is measurable, risk-based and operationally explicit. Define the intended outcome, preserve data provenance, test on representative material, use human expertise where consequences justify it, and make security and quality observable through logs and metrics. That produces a workflow that can improve as models change without forcing the organization to rebuild its governance every time a new model is released.
Verbalscripts AI is positioned around that hybrid model: AI for speed and scale, structured quality controls for consistency, and human expertise for the language, domain and edge cases where review materially changes the outcome. The right deployment is not “AI versus people”; it is a designed system that uses each where it creates the most value.
Research Notes and Sources
This article synthesizes current standards, research and publicly available vendor documentation. Pricing and product features change; verify live vendor terms before procurement. Benchmark/vendor claims are attributed as such and should not be treated as independently reproduced Verbalscripts AI results. For 2027-titled pieces, forward-looking statements are an outlook based on evidence available through September 2026 and should be refreshed before publication.
- Papineni et al., BLEU: a Method for Automatic Evaluation of Machine Translation: https://aclanthology.org/P02-1040/
- Rei et al., COMET: A Neural Framework for MT Evaluation: https://aclanthology.org/2020.emnlp-main.213/
- MQM Council - Multidimensional Quality Metrics: https://www.themqm.org/
- NIST AI Risk Management Framework 1.0: https://www.nist.gov/publications/artificial-intelligence-risk-management-framework-ai-rmf-10
- EU AI Act data governance and record-keeping provisions: https://eur-lex.europa.eu/legal-content/EN/TXT/?uri=CELEX:32024R1689
- Hugging Face Dataset Cards documentation: https://huggingface.co/docs/hub/datasets-cards
- NIST Cybersecurity Framework (CSF) 2.0: https://www.nist.gov/publications/nist-cybersecurity-framework-csf-20
- NIST SP 800-53 Rev. 5 Security and Privacy Controls: https://csrc.nist.gov/pubs/sp/800/53/r5/final
- Meta Seamless Communication research: https://ai.meta.com/research/seamless-communication/
- Meta SeamlessM4T overview: https://ai.meta.com/blog/seamless-m4t/