The real cost of AI translation is not the API sticker price alone. Buyers should model billable units, feature add-ons, storage and egress, integration, quality failures, reprocessing, human review, project management, security requirements and support. The cheapest raw rate can become the most expensive workflow if accuracy or operational fit is poor.
Key takeaways
Key Takeaways
- Define quality and acceptance criteria before selecting a model or vendor.
- Evaluate on representative material and report slice-level results, not just one average score.
- Use human review selectively where confidence is low or the consequence of an error is high.
- Capture errors and corrections in structured form so the workflow improves over time.
- Optimize total cost per accepted output, not only raw API or model consumption.
Why This Topic Matters Now
The market for AI translation contains raw APIs, managed AI platforms, hybrid human-review services and traditional language-service providers adopting AI. “AI translation vs. Traditional Translation Cost: What Changes?” is useful only if it gives buyers a common basis for comparison instead of repeating vendor-defined metrics that cannot be reconciled.
This guide translates that problem into concrete design and evaluation choices. It defines what to specify before implementation, what to measure, how to test difficult cases, where human review adds value, and which security or procurement questions should be answered before the workflow is scaled. The objective is a system that can be audited and improved, not a marketing claim that depends on ideal inputs.
The Core Technical and Operational Issues
Normalize units before comparing price sheets. Speech APIs may bill per second/minute/hour; translation systems may bill source characters, tokens, pages or subscription capacity. Convert them to your actual monthly workload and include target-language multiplication.
As of September 2026, Google Cloud publishes standard Speech-to-Text V2 pricing starting at $0.016 per processed minute for the first 500,000 monthly minutes, with dynamic batch listed at $0.003 per minute. Those numbers illustrate why raw inference can be cheap relative to review, integration and error handling; verify live pricing before publication or procurement.
Google Cloud Translation currently documents default NMT text pricing at $20 per million input characters and LLM text translation at $10 per million input characters plus $10 per million output characters; document translation has separate page-based rates. This makes “price per word” comparisons unreliable unless the billing model is normalized.
DeepL documents usage-based character billing for API plans and plan-specific limits. Enterprise buyers should compare data handling, language coverage, glossary behavior, document support and human-review costs alongside the character rate.
A Practical Enterprise Scenario
Consider an enterprise processing 100,000 units of AI translation each month. Vendor A has the lower raw price but requires twice the human review and more engineering to handle failures; Vendor B costs more per unit but delivers cleaner structured output and stronger operational controls. A TCO model can make Vendor B cheaper even when its price sheet looks worse.
Translate the Business Need Into Requirements
Start by writing a requirements profile for AI translation. Describe the source material, expected output, languages or locales, domain terminology, expected volume, latency or turnaround needs, downstream systems, security classification and the consequences of an error. A customer-support analytics pipeline can tolerate different errors from a court filing, medical record, model-training corpus or public translation. Treating those uses as equivalent creates false confidence.
Convert the requirements into acceptance criteria. Instead of “high accuracy,” specify the metric, test set, threshold, sampling method and treatment of critical errors. Instead of “fast turnaround,” define when the clock starts, what pauses it, what constitutes delivery and what happens during spikes. Instead of “secure,” specify identity controls, encryption, retention, residency, subprocessor rules and the evidence a vendor must provide. Precise requirements make later vendor comparison and QA much easier.
Compare Quality on Your Own Content
Quality for AI translation must be defined before it can be improved. Establish a reference standard, scoring rules and sampling plan, then separate model errors from workflow errors. The reference itself needs quality control: inconsistent human labels create an evaluation ceiling and can make a better system appear worse.
Combine automatic metrics with human evaluation. BLEU remains useful for reproducible lexical comparison, while semantic metrics such as COMET correlate more closely with human judgments in many research settings. Human analytic evaluation such as MQM makes error type and severity visible, including accuracy, terminology and fluency issues that a single score obscures.
Track severity as well as frequency. A missing comma and a wrong medication name should not carry the same business weight; neither should a stylistic translation choice and an omission that changes meaning. A practical program uses a critical-error taxonomy and defines which errors trigger rejection, mandatory review, customer notification or retraining.
Run a pilot on representative AI translation material before scaling. Include ordinary cases, difficult cases and high-consequence cases. Keep the same files across vendors or model versions, blind reviewers where practical, and use a pre-agreed scoring rubric. Measure quality, turnaround, operational failure rate, review effort, integration effort and cost together.
The pilot should have explicit exit criteria: pass, fail or proceed with conditions. Record unresolved risks and customer responsibilities. If the pilot depends on one-off manual intervention by the vendor, distinguish that from the production design; otherwise the team may approve a quality level that cannot be reproduced at scale.
Compare Providers With a Weighted Scorecard
Compare providers using a weighted scorecard tied to your AI translation use case. Typical dimensions are representative quality, language/locale coverage, latency and throughput, human-review capability, API and file-format support, security and privacy, data residency, administration, observability, support, roadmap stability and total cost. Weighting forces stakeholders to state what actually matters instead of choosing the vendor with the strongest demo.
Require evidence for each score. “Supports 100 languages” should become a tested list of locales and quality results. “SOC 2” should become the scope and date of the report plus any customer responsibilities. “99% accuracy” should become the dataset, metric, normalization and sample size behind the claim. If evidence is unavailable, mark the criterion unknown rather than assuming the marketing statement is comparable.
Model Total Cost, Not Just the Sticker Rate
Price AI translation in layers. The first layer is model or API consumption; the second is platform and infrastructure; the third is quality assurance and human review; the fourth is operational overhead such as integration, project management, security review and support; and the fifth is the expected cost of errors or rework. A purchase decision based only on layer one is rarely an enterprise total-cost model.
Cloud translation APIs commonly meter characters or tokens; for example, Google Cloud publishes character-based pricing for NMT and LLM translation, while DeepL documents character-based API billing and plan limits. Human review is normally priced separately by word, hour, project or managed-service agreement.
Build scenarios for expected, peak and difficult content. Include the percentage routed to human review, average edit time, reprocessing rate, number of target languages, storage/egress, minimum commitments and volume discounts. A higher unit price can still produce a lower total cost if it materially reduces review or engineering effort; the reverse is also true when premium features do not improve the actual use case.
Decide Where Human Review Belongs
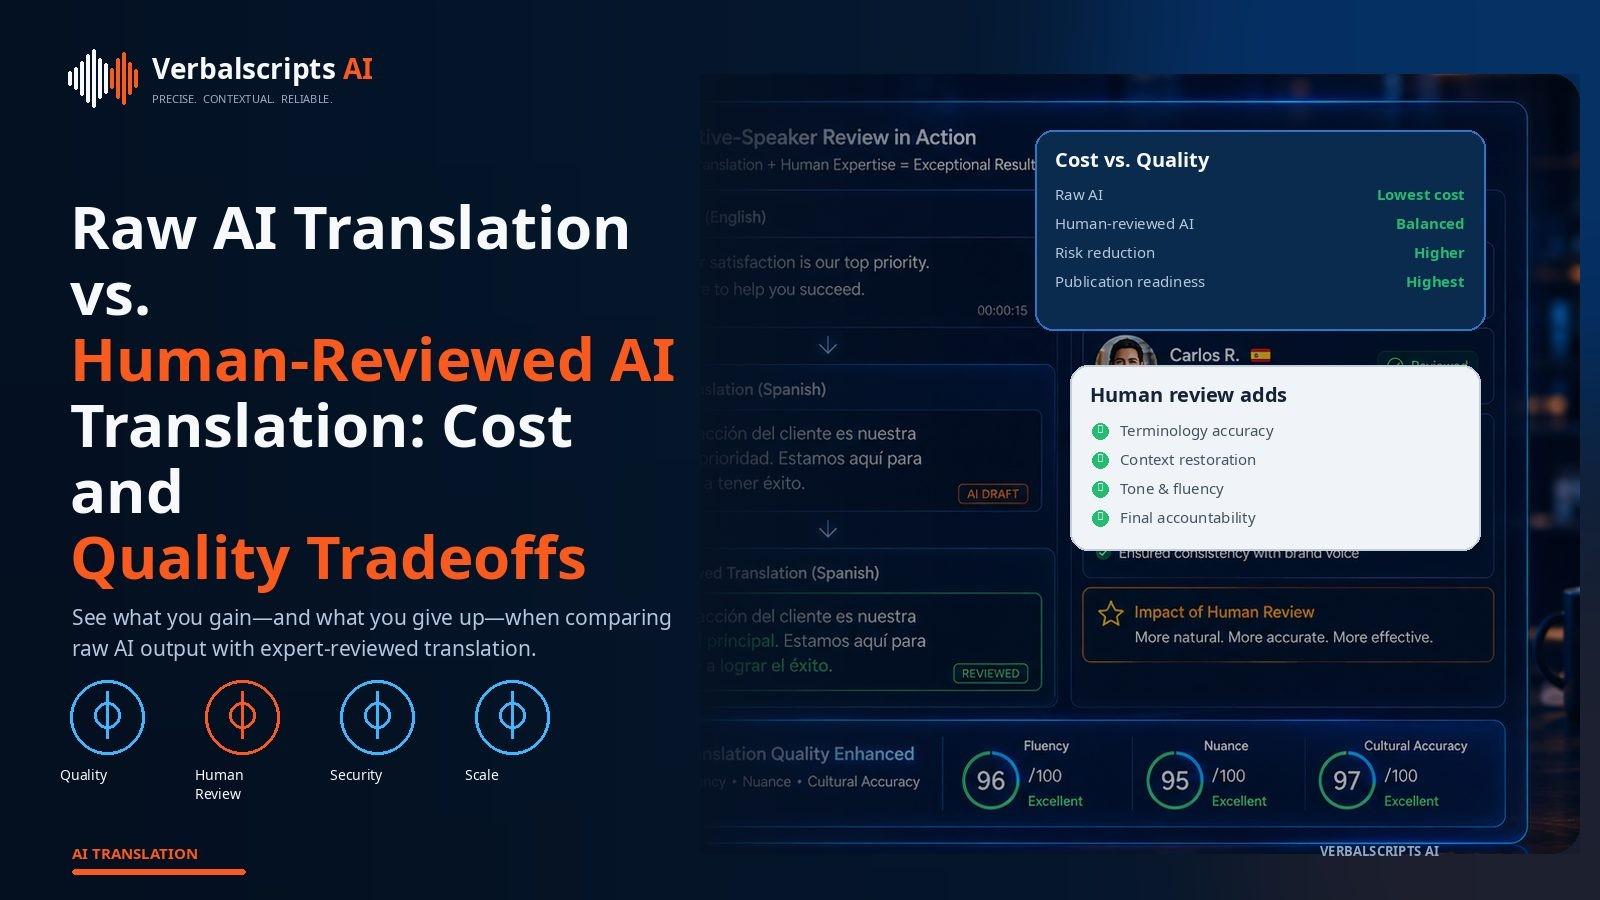
There are three common service levels: raw AI, human-reviewed AI and fully human production. Raw AI maximizes speed and minimizes marginal cost but exposes model errors directly. Human-reviewed AI uses automation for the first pass and people for correction or verification, which often provides a strong quality-cost balance. Fully human workflows can be appropriate for exceptionally sensitive, complex or low-resource content, but they still need documented QA and are not automatically error-free.
Choose by consequence, not ideology. Internal search notes, rough captions and discovery analytics may accept raw AI. Customer-facing translations, legal records, research data, healthcare content or training/evaluation references may justify review. Some organizations use dynamic routing: low-risk material is automated, while confidence, domain or customer rules trigger review. That usually scales better than forcing one service level onto every file.
Human review should be risk-based rather than all-or-nothing. Route cases using confidence, domain, language, customer requirements and the potential cost of an error. High-confidence, low-risk material may pass automatically after sampling; low-confidence or high-consequence material should receive full review. Sampling should also include apparently easy cases so silent regressions are not missed.
Review instructions need examples, not only principles. Define how to handle names, numbers, abbreviations, speaker identity, inaudible content, code-switching, terminology, omissions, additions, formatting and ambiguous source material. Calibrate reviewers on a shared set, compare disagreement, adjudicate recurring edge cases and update the guideline. Human review becomes more consistent when reviewers are measuring the same definition of “correct.”
Capture corrections structurally. Store the original model output, corrected output, error category, severity and context where permitted. That turns review from a cost center into evaluation and improvement data, while maintaining a clear audit trail of what changed and by whom.
Security, Privacy and Enterprise Controls
Security should be mapped to the data lifecycle, not added only at upload. Use TLS for data in transit and strong encryption for stored source files, intermediate artifacts, outputs and backups. Centralize identity, require multi-factor authentication for privileged access, implement least privilege and role separation, and use short-lived credentials or signed URLs for automated retrieval. Secrets should be managed outside code and rotated through a defined process.
Logging must support accountability without becoming a second copy of sensitive content. Record who accessed what, when, from which service or role, and what action occurred; avoid writing transcript text, document content, access tokens or unnecessary PII into operational logs. Protect logs from modification or unauthorized deletion and define retention based on investigation and compliance needs. NIST CSF 2.0 places governance alongside identify, protect, detect, respond and recover, which is a useful reminder that controls require ownership and ongoing review, not just technology.
Vendor security reviews should examine subprocessors, data locations, breach-notification commitments, vulnerability management, penetration testing, key management, backup practices, personnel access, secure development and evidence such as independent assurance reports. Certifications can reduce due-diligence effort, but they do not prove that a particular workflow is configured safely.
Privacy requirements are easiest to satisfy when they are translated into system behavior. Define the purpose of processing, categories of personal data, legal or contractual basis, permitted users, retention period, approved processing locations and deletion workflow before data enters the pipeline. Keep customer data isolated by tenant and prevent support or quality staff from browsing content without a work-related reason.
Apply data minimization: collect only fields and content needed for the purpose, restrict reuse, and avoid keeping source data “just in case.” If content may later be used for analytics or model improvement, treat that as a separate purpose with its own authority, notice, contract terms and controls.
For programs that touch EU personal data, GDPR principles such as purpose limitation, data minimization and storage limitation are directly relevant, and cross-border transfers require an appropriate legal mechanism. Similar principles are useful even when a project is outside GDPR because they force the team to justify data collection, access and retention instead of defaulting to unlimited reuse.
Contract, RFP and Statement-of-Work Requirements
A strong RFP or statement of work uses measurable requirements. Define scope and volumes; source formats; languages/locales; expected outputs; model and human-review options; quality and acceptance metrics; turnaround and priority classes; support response; security; data retention and deletion; processing regions; subprocessors; integration; reporting; change control; business continuity; pricing assumptions; and ownership/licensing of outputs and improvement data.
Avoid clauses that sound strict but cannot be tested. “Best-in-class accuracy” is weaker than a threshold on a representative evaluation set. “Immediate support” is weaker than a severity matrix with response and restoration targets. “Delete data promptly” is weaker than explicit retention periods for source files, outputs, logs and backups. Procurement language should create observable obligations.
Service levels should separate quality from availability and turnaround. For quality, define the metric and sampling method plus a critical-error standard. For turnaround, specify service windows, queue cutoffs, pause conditions and batch-volume assumptions. For platform availability, specify the API or portal boundary, exclusions, maintenance rules and remedies. For support, use severity-based response targets and escalation paths.
Also define what happens when volume or language mix changes. A provider may meet a two-hour turnaround at 100 files per day and fail at 10,000. Capacity commitments, concurrency, rate limits and surge procedures belong in the SLA when the workflow is business-critical. Review performance monthly or quarterly; an SLA that is never measured becomes a decorative contract term.
Implementation Decision Framework
Implement AI translation in phases. First, inventory the use cases and classify risk. Second, define inputs, outputs, quality and security requirements. Third, build a representative evaluation set and baseline the current workflow. Fourth, pilot the new workflow with controlled users. Fifth, automate observability, review routing and reporting. Sixth, expand languages, volume or use cases only after the previous phase is stable.
Assign owners across product/operations, engineering, security/privacy, language or domain quality, and procurement/legal. Most failures occur at the boundaries: a technically strong model is deployed without review guidance; a secure API feeds an insecure shared drive; a multilingual program has global tooling but no native-language QA ownership. Clear RACI and escalation rules are as important as the model configuration.
Frequently Asked Questions
AI Translation vs. Traditional Translation Cost: What Changes?
Model effective cost per accepted output: API or platform charges plus human review, reprocessing, integration, storage, support and the expected cost of quality failures. Normalize vendor billing units before comparison.
What should enterprises look for in AI translation?
Enterprises should evaluate AI translation against their own data, required languages, workflow, risk level and downstream use. The most important buying criteria are representative quality, operational fit, security, observability, human-review options and total cost, not a generic benchmark claim.
How should AI translation quality be measured?
Use a representative, human-verified test set and more than one metric. Combine an aggregate score with slice-level analysis and a critical-error taxonomy. For high-consequence speech or translation, include qualified human evaluation because a single automatic metric can hide errors in names, numbers, terminology, omissions or meaning.
When is human review necessary for AI translation?
Human review is most valuable when errors have meaningful consequences, the content is difficult or specialized, the language is low-resource, or the output will become a reference artifact. Risk-based routing is usually more efficient than reviewing every file or reviewing none.
What drives the real cost of AI translation?
Model effective cost per accepted output: API or platform charges plus human review, reprocessing, integration, storage, support and the expected cost of quality failures. Normalize vendor billing units before comparison.
Conclusion
The strongest approach to AI translation vs traditional translation cost what changes is measurable, risk-based and operationally explicit. Define the intended outcome, preserve data provenance, test on representative material, use human expertise where consequences justify it, and make security and quality observable through logs and metrics. That produces a workflow that can improve as models change without forcing the organization to rebuild its governance every time a new model is released.
Verbalscripts AI is positioned around that hybrid model: AI for speed and scale, structured quality controls for consistency, and human expertise for the language, domain and edge cases where review materially changes the outcome. The right deployment is not “AI versus people”; it is a designed system that uses each where it creates the most value.
Research Notes and Sources
This article synthesizes current standards, research and publicly available vendor documentation. Pricing and product features change; verify live vendor terms before procurement. Benchmark/vendor claims are attributed as such and should not be treated as independently reproduced Verbalscripts AI results. For 2027-titled pieces, forward-looking statements are an outlook based on evidence available through September 2026 and should be refreshed before publication.
- Google Cloud Translation pricing: https://cloud.google.com/products/translate/pricing
- DeepL API usage and billing guidance: https://support.deepl.com/hc/en-us/articles/360020685720-Usage-count-and-billing-in-DeepL-API
- DeepL 2026 translation API buyer guidance: https://www.deepl.com/en/translation-api-buyers-guide
- NIST Cybersecurity Framework (CSF) 2.0: https://www.nist.gov/publications/nist-cybersecurity-framework-csf-20
- NIST SP 800-53 Rev. 5 Security and Privacy Controls: https://csrc.nist.gov/pubs/sp/800/53/r5/final
- NIST AI Risk Management Framework 1.0: https://www.nist.gov/publications/artificial-intelligence-risk-management-framework-ai-rmf-10