For operations, product, content and AI teams that need reliable speech-to-text output, speaker diarization is rarely just a conversion problem. The transcript can become input to search, review, evidence, analytics, captions, summaries, records or another AI system. Errors therefore have uneven impact: a missed filler may be harmless, while a wrong name, number, speaker label or legal term can change how the output is used.
For the product workflow, see AI Transcription. This guide focuses on the practical quality, workflow and buyer questions around the topic rather than product mechanics.
Key takeaways
Key takeaways
- Treat speaker diarization as an end-to-end workflow, not just a model output.
- Evaluate quality on representative material and include speaker-turn boundaries, speaker-count estimation and overlapping speech in the test plan.
- Use human review where the cost of a wrong word, speaker, number, name or translation is materially higher than the cost of checking it.
- Keep source, instructions, output and revisions traceable so teams can reproduce and audit important corrections.
- Judge the final deliverable by its downstream task: search, evidence, captions, analytics, localization, records, accessibility or another AI workflow.
1. Understanding speaker diarization
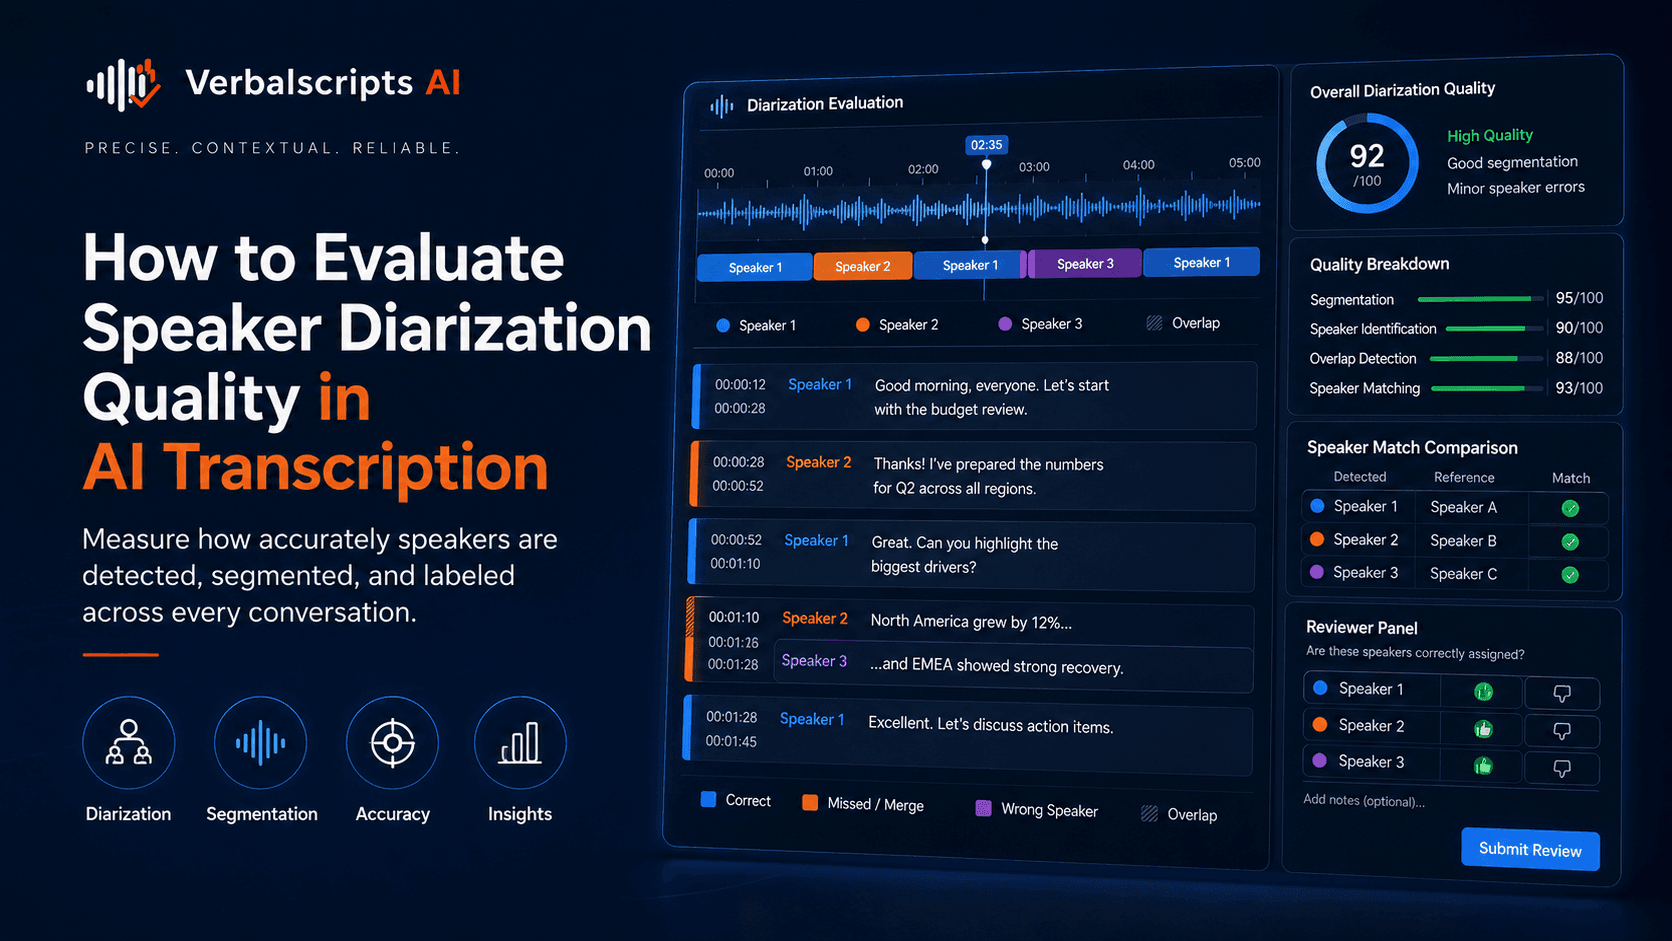
Speaker diarization segments a recording into regions associated with distinct speaker clusters. A typical pipeline detects speech, extracts speaker representations, groups similar segments and then smooths the boundaries. The result may be Speaker 1, Speaker 2 and so on; those labels are clusters, not verified identities.
Diarization becomes difficult when speakers have similar voices, turns are very short, people interrupt each other, or the recording mixes participants through one microphone. The word sequence may be correct while the attribution is wrong, which is why diarization quality should be evaluated separately from WER.
For high-stakes records, map automatic clusters to real identities only with supporting context and review. Names in an attendee list can help, but they do not prove which cluster belongs to which person.
2. What determines quality
Speaker-Turn Boundaries. Diarization must decide where one speaker stops and another begins. Short interjections and rapid turn-taking are common boundary errors and can cascade into mislabeled transcript spans.
Speaker-Count Estimation. If the system assumes too few speakers, voices may be merged; too many can split one person into multiple labels. Long recordings and similar voices make this harder.
Overlapping Speech. When people talk at the same time, a single mixed channel may contain competing speech. Recognition and diarization can both fail even when each speaker is individually clear.
Label Consistency Across Long Recordings. A useful transcript should keep the same speaker mapped to the same label across the file. Drift is especially disruptive in meetings, depositions and interviews.
Manual Verification When Identity Matters. Automatic diarization normally creates speaker clusters such as Speaker 1 and Speaker 2. Mapping those clusters to real names should be verified when attribution has legal, operational or reputational consequences.
Representative Test Sets. Representative Test Sets affects whether speaker diarization remains reliable in production. Define the requirement, test it on representative material and establish what happens when the result falls outside tolerance.
These factors interact. A glossary can reduce terminology errors but cannot recover speech lost to clipping; a clean microphone can improve recognition but cannot resolve an ambiguous name without context. The safest way to understand performance is to test the complete workflow on representative material.
3. A practical decision framework
The point of the framework is not to force every project into the same quality tier. It is to make tradeoffs explicit. A searchable internal archive, for example, may value throughput and broad recall; a legal or medical deliverable may prioritize exact names, numbers, attribution and review even if that adds time.
4. Recommended workflow
1. Build a representative test set. Sample the languages, accents, channels, speaker counts, audio quality and domain terminology that appear in real production work.
2. Create or verify the reference transcript. The reference must itself be accurate and consistently normalized; otherwise scoring can reward or penalize the wrong behavior.
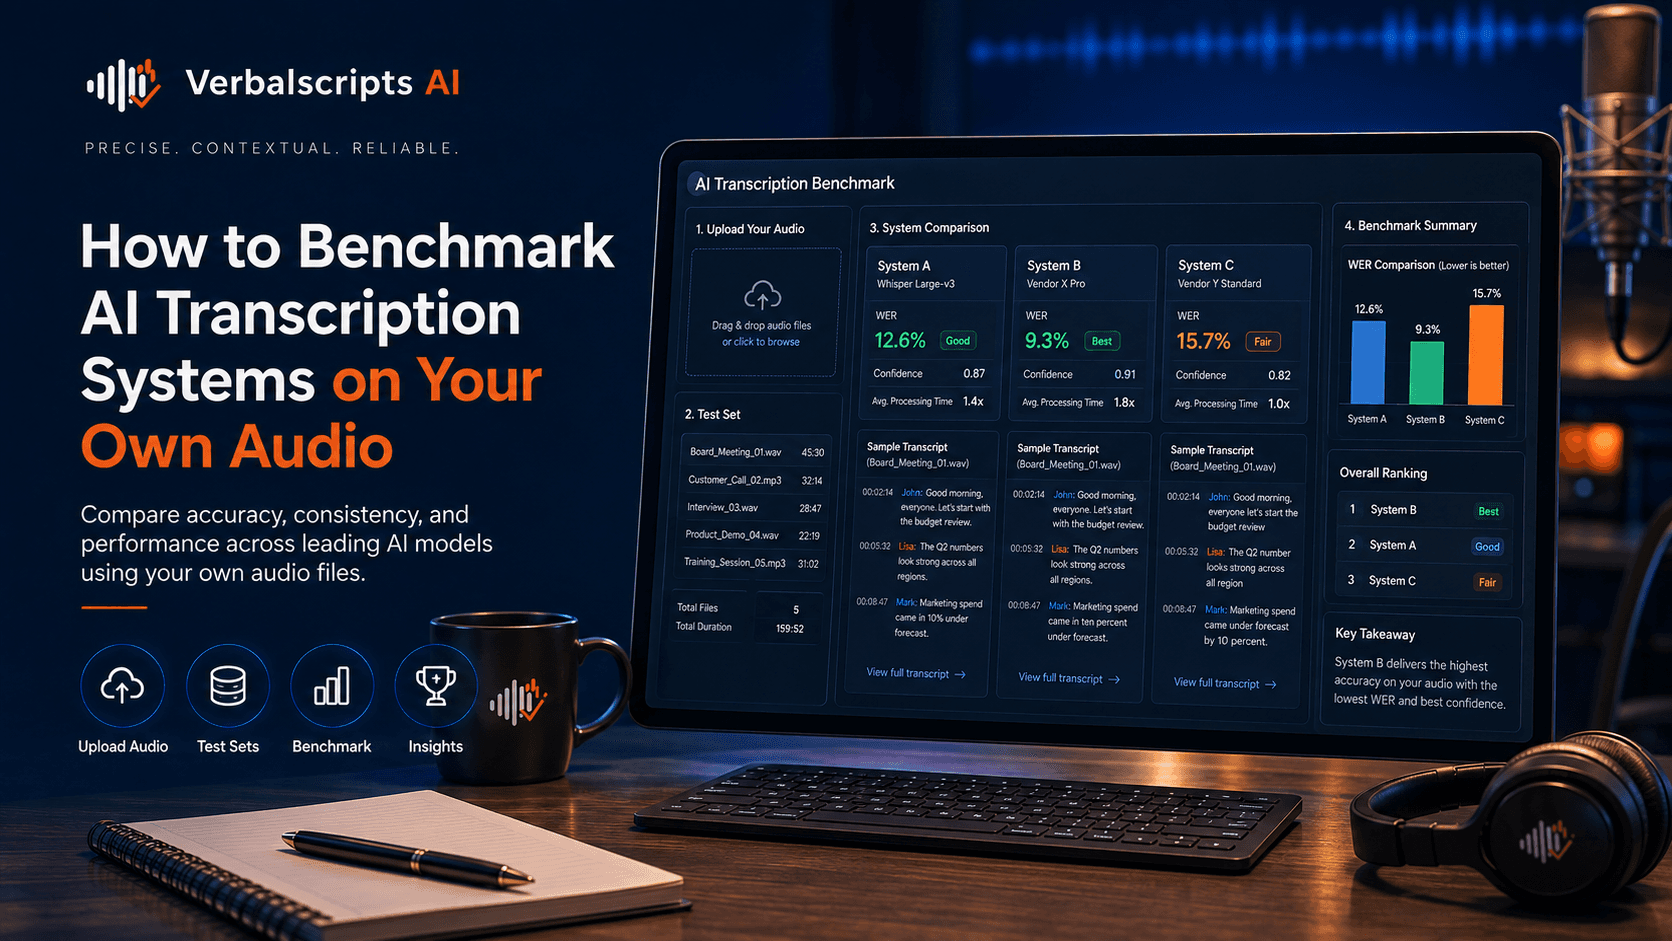
3. Run every system under matched conditions. Use the same source files, segmentation, language settings and preprocessing so results are comparable.
4. Score multiple quality dimensions. Measure word errors, but also speaker attribution, critical entities, timestamps, formatting and task-specific errors where they matter.
5. Review errors qualitatively. Look at which errors occurred, not only how many. A system with similar average WER can have very different failure patterns and business impact.
5. Common failure modes to avoid
- Assuming diarization equals verified identity. Build a specific control for this failure mode rather than relying on a general accuracy promise.
- Merging short interjections into the wrong speaker. Build a specific control for this failure mode rather than relying on a general accuracy promise.
- Changing speaker labels mid-recording. Build a specific control for this failure mode rather than relying on a general accuracy promise.
- Ignoring overlap and crosstalk. Build a specific control for this failure mode rather than relying on a general accuracy promise.
- Evaluating words but not attribution. Build a specific control for this failure mode rather than relying on a general accuracy promise.
- Benchmarking on vendor demos. Build a specific control for this failure mode rather than relying on a general accuracy promise.
Failure analysis is especially valuable because average metrics can hide concentrated problems. A system may perform well overall but repeatedly fail on a particular accent, speaker role, language pair, product name or recording channel. Those recurring errors are often more actionable than a single global score.
6. How to evaluate a system or provider
Representative evidence. Use source files that reflect your normal work plus realistic edge cases. Ask for results on your material, not only benchmark claims.
Transparent quality definition. Define what counts as an error and what matters most: words, speakers, timestamps, names, numbers, formatting, meaning, omissions or downstream task success.
Review and correction process. Understand what is automatic, what receives human review, who performs that review, what reference materials are used, and how corrections are tracked.
Security and retention. Document how files are transferred, accessed, stored, retained and deleted. Sensitive workflows need controls proportional to the data and the consequences of exposure.
Operational fit. Check supported formats, turnaround, scale, API or batch behavior, revision handling, support, and whether the final output integrates cleanly with your tools.
For model and workflow evaluation, explore Verbalscripts AI Evaluation and use a pilot that mirrors your production mix.
7. Production implementation notes for speaker diarization
- Define the acceptance criteria for speaker diarization before processing, including what errors are material and what output format the next system expects.
- Keep the original source and the first-pass output so reviewers can verify corrections and teams can reproduce failures.
- Use reference material such as speaker lists, agendas, glossaries and known names when it improves ambiguity resolution.
- Track recurring error categories rather than only an average score; repeated failure patterns point to the best process improvements.
- Revalidate timestamps, speaker labels and structured metadata after substantive text edits because downstream alignment can break silently.
8. Illustrative workflow example
Consider a team processing a representative batch for speaker diarization. The team keeps the original files, defines speaker/timestamp/style rules, supplies known names and terminology, generates the first pass, routes high-risk or uncertain spans to review, and records corrections before export. The example is illustrative rather than a client case study; its purpose is to show how model output, review and document controls fit together.
During the pilot, the team records not only an overall error rate but which errors consume reviewer time: speaker attribution, names, numbers, overlap, unclear audio, timing or formatting. That information makes the next iteration measurable and prevents quality work from becoming subjective cleanup.
9. Related Verbalscripts AI resources
- AI Transcription: use this page when the reader is ready to move from education to the relevant product, workflow or buying decision.
- AI Evaluation: use this page when the reader is ready to move from education to the relevant product, workflow or buying decision.
- Resources: use this page when the reader is ready to move from education to the relevant product, workflow or buying decision.
- Pricing: use this page when the reader is ready to move from education to the relevant product, workflow or buying decision.
- Real-Time AI Transcription: Accuracy, Latency and Speaker Identification: supporting cluster article.
- How to Benchmark AI Transcription Systems on Your Own Audio: supporting cluster article.
- AI Transcription: The Complete Guide to Turning Audio and Video Into Accurate Text: supporting cluster article.
Frequently asked questions
What is the most important quality measure for speaker diarization?
There is no single universal measure. Word accuracy is important, but the best metric depends on the use case. Speaker labels, critical names and numbers, timestamps, formatting, completeness and downstream usability may be equally important.
When should speaker diarization include human review?
Use more human review as the cost of an error rises. Legal, medical, regulated, public-facing, evidentiary and customer-deliverable transcripts generally justify deeper verification than low-risk internal search or rough notes.
How can I test a transcription provider fairly?
Use a representative test pack, keep source files and instructions identical, create or verify a high-quality reference, score the same dimensions for every provider, and examine the types of errors rather than relying on one average number.
Does better audio always improve AI transcription?
Better capture usually helps, but it is not the only factor. Accents, language, terminology, overlap, channel, speaker count and model/domain fit can still affect output even with technically clean audio.
What should happen when the audio is unclear?
The workflow should avoid guessing. Mark uncertainty consistently, preserve timestamps where useful, try careful re-listening or appropriate enhancement, and escalate material passages to human review when the wording matters.
Final takeaway
How to Evaluate Speaker Diarization Quality in AI Transcription is ultimately a workflow design question. The strongest implementations define the required output, test real source material, measure the errors that matter, protect sensitive content and add human review where the consequences justify it. That approach is more durable than choosing a system from a headline accuracy number or a clean demo clip.
Next step: Explore AI Transcription with Verbalscripts AI or review pricing if you are comparing implementation options.
Authoritative external references
Use external links to support definitions, standards, security guidance and accessibility or platform-specific facts. Avoid over-linking to competitor marketing pages when a standards body, regulator or primary documentation source is available.
- NIST Speaker Recognition Evaluation: National Institute of Standards and Technology; useful for evaluation of speaker-recognition technology and performance measurement.
- NIST AI Risk Management Framework: National Institute of Standards and Technology; useful for trustworthiness, measurement, governance and AI risk management.
- NIST SCTK / sclite scoring documentation: NIST; useful for reference/hypothesis alignment and word-error scoring.