For procurement, operations, information-security and AI program leaders comparing vendors, transcription RFPs is rarely just a conversion problem. The transcript can become input to search, review, evidence, analytics, captions, summaries, records or another AI system. Errors therefore have uneven impact: a missed filler may be harmless, while a wrong name, number, speaker label or legal term can change how the output is used.
For the product workflow, see AI Transcription. This guide focuses on the practical quality, workflow and buyer questions around the topic rather than product mechanics.
Key takeaways
Key takeaways
- Treat transcription RFPs as an end-to-end workflow, not just a model output.
- Evaluate quality on representative material and include queueing and concurrency, consistent configuration and quality sampling in the test plan.
- Use human review where the cost of a wrong word, speaker, number, name or translation is materially higher than the cost of checking it.
- Keep source, instructions, output and revisions traceable so teams can reproduce and audit important corrections.
- Judge the final deliverable by its downstream task: search, evidence, captions, analytics, localization, records, accessibility or another AI workflow.
1. Understanding transcription RFPs
Transcription rfps turns transcription into an operations problem as much as a model problem. Hundreds or thousands of hours introduce queues, retries, concurrency, configuration drift, file tracking, QA sampling and cost observability that are invisible in a one-file demo.
A scalable pipeline assigns stable IDs, records the processing configuration, prevents duplicate jobs, separates failures from completed work and keeps the source-to-output relationship intact. Quality monitoring should be sliced by language, channel, customer and other meaningful domains.
Scale the review system with the processing system. Throughput is not useful if QA becomes the bottleneck or if higher volume hides a quality regression in a minority of files.
2. What determines quality
Queueing And Concurrency. High-volume workflows need predictable job orchestration so bursts do not create hidden backlogs or starve priority files.
Consistent Configuration. Consistent Configuration affects whether transcription RFPs remains reliable in production. Define the requirement, test it on representative material and establish what happens when the result falls outside tolerance.
Quality Sampling. Scale requires a measurement plan. Use slices and targeted QA so throughput does not conceal quality drift in a language, channel or customer segment.
Failure Recovery. Jobs fail. Idempotent retries, stable identifiers and clear status prevent duplicate processing and lost files.
Cost And Throughput Observability. Cost And Throughput Observability affects whether transcription RFPs remains reliable in production. Define the requirement, test it on representative material and establish what happens when the result falls outside tolerance.
Unit Price Versus Total Workflow Cost. Headline per-minute rates ignore correction labor, integration effort, project management and the cost of unusable output. Compare total cost to a defined acceptance level.
These factors interact. A glossary can reduce terminology errors but cannot recover speech lost to clipping; a clean microphone can improve recognition but cannot resolve an ambiguous name without context. The safest way to understand performance is to test the complete workflow on representative material.
3. A practical decision framework
The point of the framework is not to force every project into the same quality tier. It is to make tradeoffs explicit. A searchable internal archive, for example, may value throughput and broad recall; a legal or medical deliverable may prioritize exact names, numbers, attribution and review even if that adds time.
4. Recommended workflow
1. Define the acceptance criteria. Write down required accuracy dimensions, output formats, turnaround, speaker labeling, review depth, security, retention, revision and support expectations.
2. Create a realistic test pack. Include normal files and difficult edge cases. Avoid choosing a provider from a polished demo or a handful of clean clips.
3. Compare complete deliverables. Normalize quotes so you know what is included: raw AI, human review, formatting, timestamps, captions, revisions, project management and integration.
4. Review security and operational controls. Confirm access, data handling, retention, deletion, incident response, API security and any industry-specific obligations relevant to your files.
5. Pilot, measure and then scale. Start with a bounded production sample, measure quality and rework, refine instructions and only then expand volume or automation.
5. Common failure modes to avoid
- Treating every file as identical. Build a specific control for this failure mode rather than relying on a general accuracy promise.
- Scaling throughput faster than QA capacity. Build a specific control for this failure mode rather than relying on a general accuracy promise.
- Reprocessing the same files accidentally. Build a specific control for this failure mode rather than relying on a general accuracy promise.
- Losing source-to-output traceability. Build a specific control for this failure mode rather than relying on a general accuracy promise.
- Using averages that hide poor subgroups. Build a specific control for this failure mode rather than relying on a general accuracy promise.
- Comparing headline rates without matching deliverables. Build a specific control for this failure mode rather than relying on a general accuracy promise.
Failure analysis is especially valuable because average metrics can hide concentrated problems. A system may perform well overall but repeatedly fail on a particular accent, speaker role, language pair, product name or recording channel. Those recurring errors are often more actionable than a single global score.
6. How to evaluate a system or provider
Representative evidence. Use source files that reflect your normal work plus realistic edge cases. Ask for results on your material, not only benchmark claims.
Transparent quality definition. Define what counts as an error and what matters most: words, speakers, timestamps, names, numbers, formatting, meaning, omissions or downstream task success.
Review and correction process. Understand what is automatic, what receives human review, who performs that review, what reference materials are used, and how corrections are tracked.
Security and retention. Document how files are transferred, accessed, stored, retained and deleted. Sensitive workflows need controls proportional to the data and the consequences of exposure.
Operational fit. Check supported formats, turnaround, scale, API or batch behavior, revision handling, support, and whether the final output integrates cleanly with your tools.
For model and workflow evaluation, explore Verbalscripts AI Evaluation and use a pilot that mirrors your production mix.
7. Production implementation notes for transcription RFPs
- Use stable file and job identifiers from ingest through export so retries, revisions and billing can be reconciled.
- Make retries idempotent and observable; a transient failure should not create duplicate jobs or orphaned outputs.
- Keep sensitive transcript text out of unnecessary application logs and monitoring payloads.
- Version processing settings and glossaries so a quality change can be traced to configuration rather than guessed after the fact.
- Build QA sampling into the pipeline from the start instead of treating review as a manual patch after scale creates problems.
8. Illustrative workflow example
Consider a team processing a representative batch for transcription RFPs. The team keeps the original files, defines speaker/timestamp/style rules, supplies known names and terminology, generates the first pass, routes high-risk or uncertain spans to review, and records corrections before export. The example is illustrative rather than a client case study; its purpose is to show how model output, review and document controls fit together.
During the pilot, the team records not only an overall error rate but which errors consume reviewer time: speaker attribution, names, numbers, overlap, unclear audio, timing or formatting. That information makes the next iteration measurable and prevents quality work from becoming subjective cleanup.
9. Related Verbalscripts AI resources
- AI Transcription: use this page when the reader is ready to move from education to the relevant product, workflow or buying decision.
- Pricing: use this page when the reader is ready to move from education to the relevant product, workflow or buying decision.
- AI Data: use this page when the reader is ready to move from education to the relevant product, workflow or buying decision.
- Resources: use this page when the reader is ready to move from education to the relevant product, workflow or buying decision.
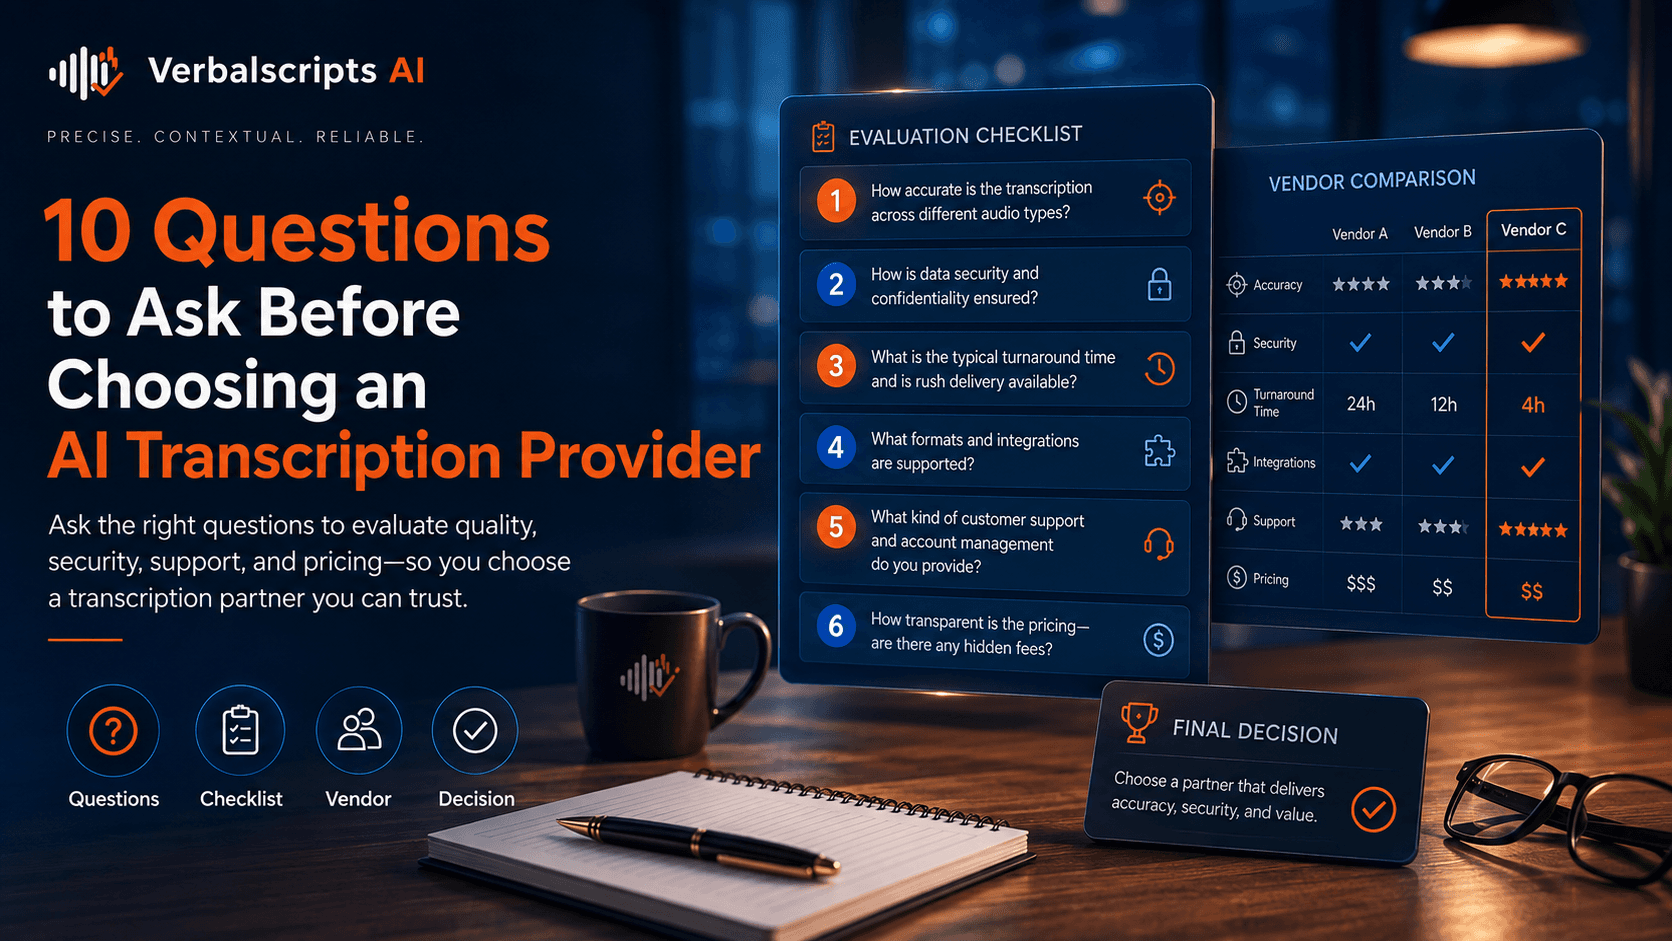
- 10 Questions to Ask Before Choosing an AI Transcription Provider: supporting cluster article.
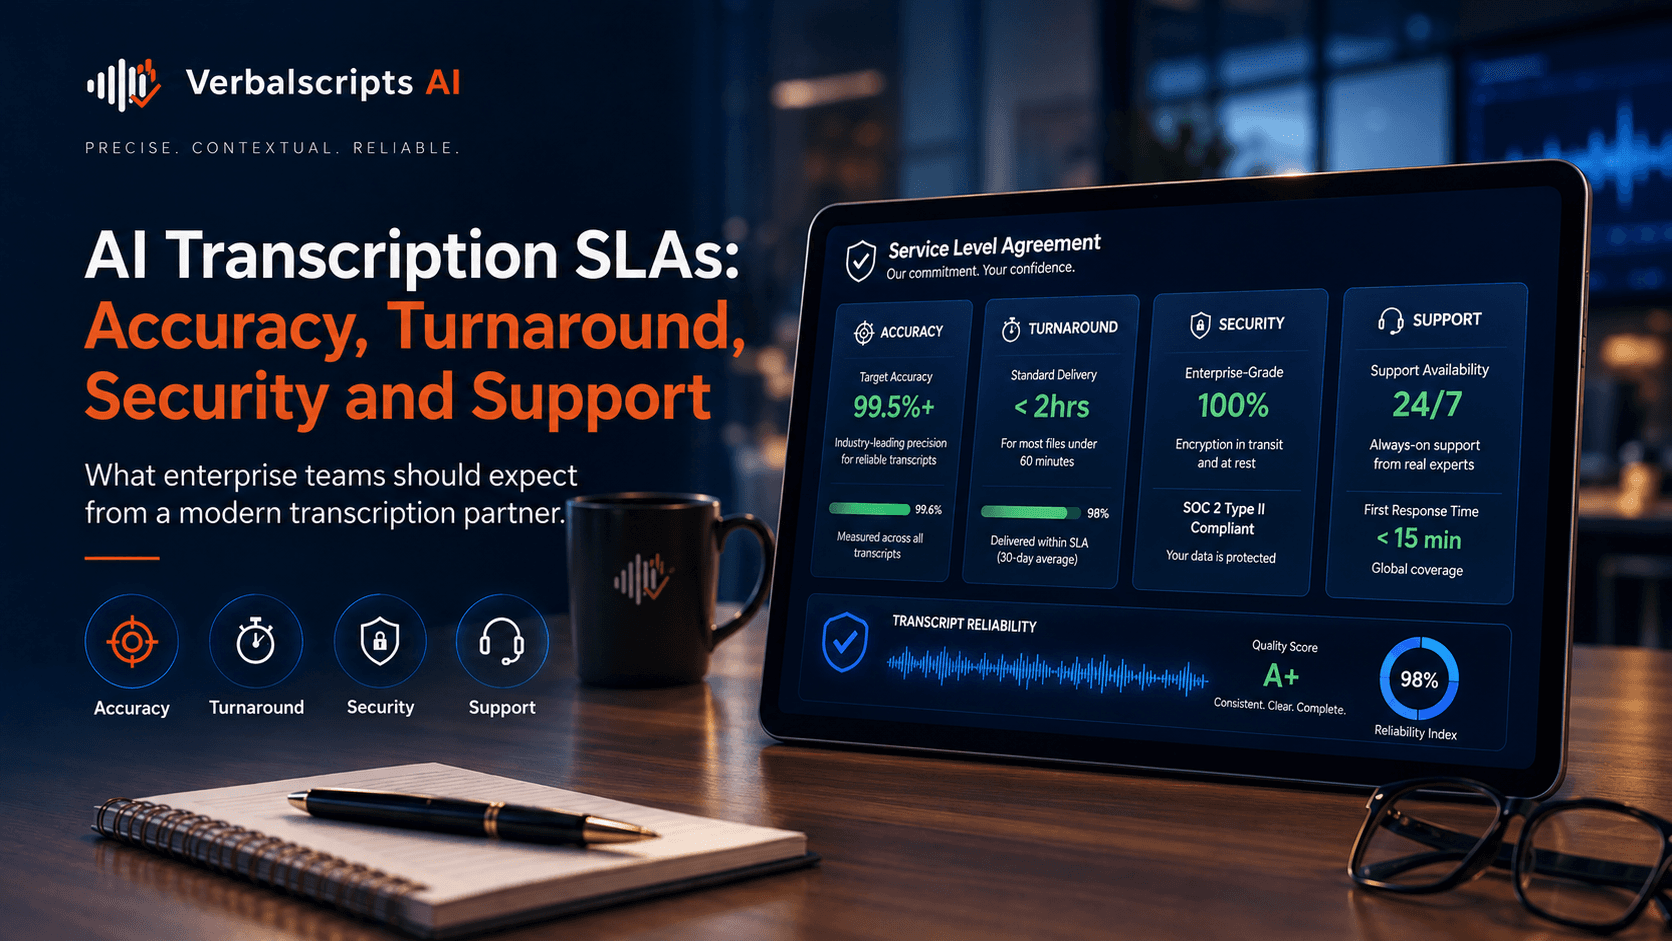
- AI Transcription SLAs: Accuracy, Turnaround, Security and Support: supporting cluster article.
- AI Transcription: The Complete Guide to Turning Audio and Video Into Accurate Text: supporting cluster article.
Frequently asked questions
What is the most important quality measure for transcription RFPs?
There is no single universal measure. Word accuracy is important, but the best metric depends on the use case. Speaker labels, critical names and numbers, timestamps, formatting, completeness and downstream usability may be equally important.
When should transcription RFPs include human review?
Use more human review as the cost of an error rises. Legal, medical, regulated, public-facing, evidentiary and customer-deliverable transcripts generally justify deeper verification than low-risk internal search or rough notes.
How can I test a transcription provider fairly?
Use a representative test pack, keep source files and instructions identical, create or verify a high-quality reference, score the same dimensions for every provider, and examine the types of errors rather than relying on one average number.
Does better audio always improve AI transcription?
Better capture usually helps, but it is not the only factor. Accents, language, terminology, overlap, channel, speaker count and model/domain fit can still affect output even with technically clean audio.
What should happen when the audio is unclear?
The workflow should avoid guessing. Mark uncertainty consistently, preserve timestamps where useful, try careful re-listening or appropriate enhancement, and escalate material passages to human review when the wording matters.
Final takeaway
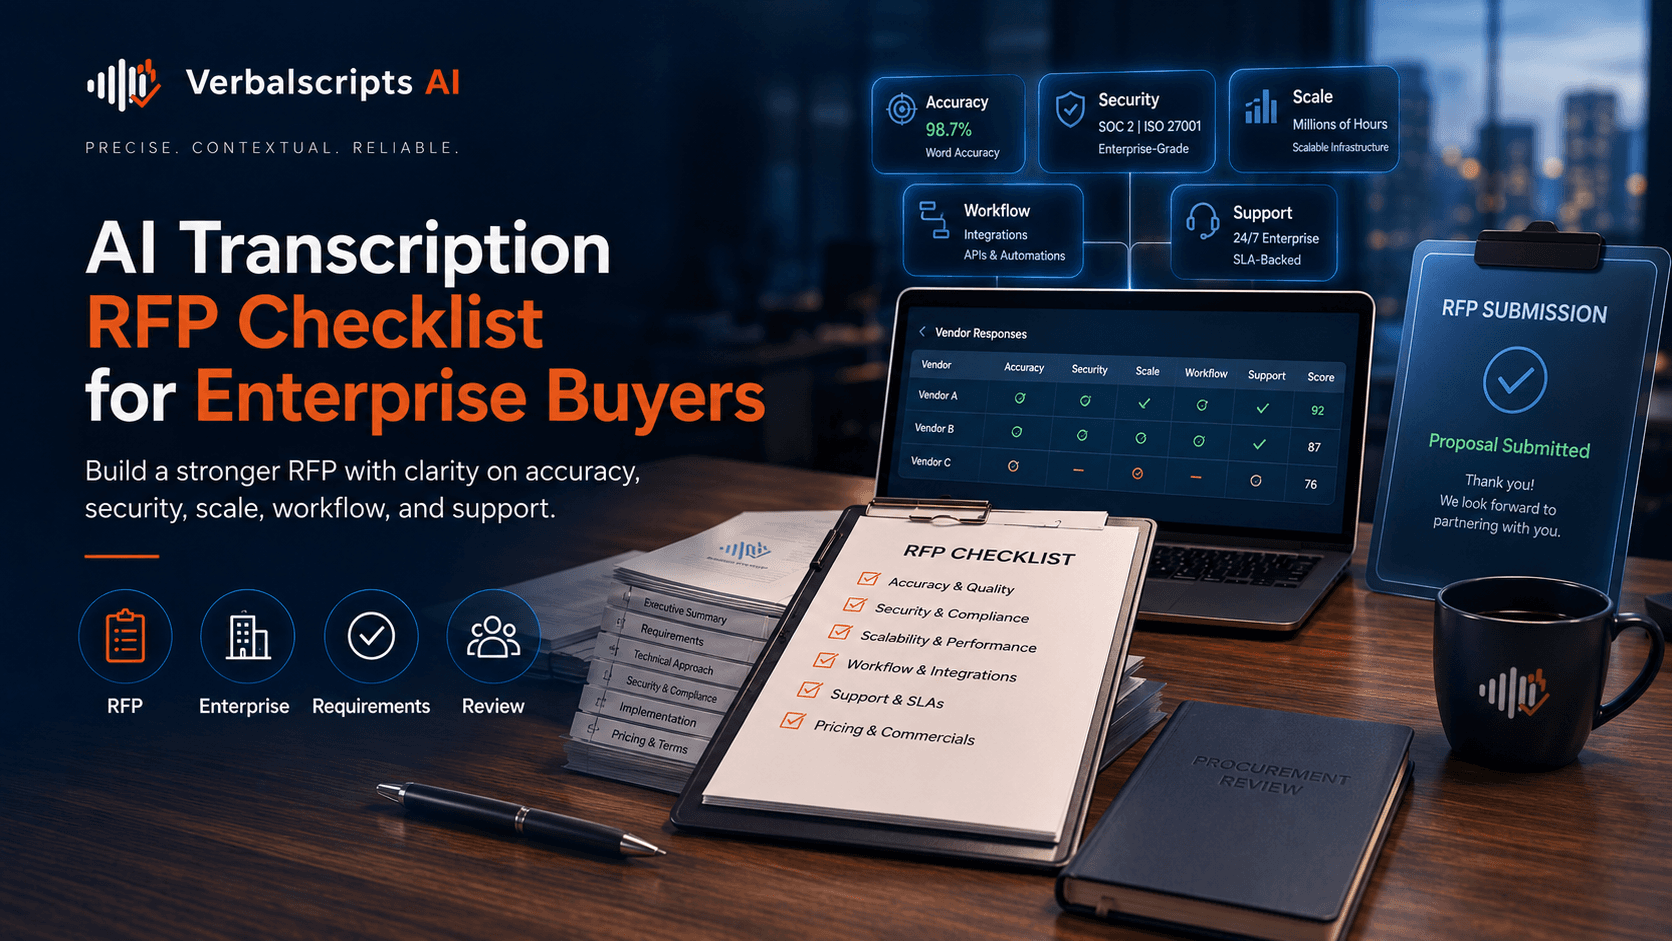
AI Transcription RFP Checklist for Enterprise Buyers is ultimately a workflow design question. The strongest implementations define the required output, test real source material, measure the errors that matter, protect sensitive content and add human review where the consequences justify it. That approach is more durable than choosing a system from a headline accuracy number or a clean demo clip.
Next step: Explore AI Transcription with Verbalscripts AI or review pricing if you are comparing implementation options.
Authoritative external references
Use external links to support definitions, standards, security guidance and accessibility or platform-specific facts. Avoid over-linking to competitor marketing pages when a standards body, regulator or primary documentation source is available.
- NIST AI Risk Management Framework: National Institute of Standards and Technology; useful for trustworthiness, measurement, governance and AI risk management.
- Data Security Guidance: U.S. Federal Trade Commission; useful for practical business data-security guidance.