QUICK ANSWER
AI Transcription for Insurance Claims and Recorded Statements describes a structured workflow for turning source content into a usable, reviewable language asset. Automation can accelerate the first pass, but quality depends on preserving context, structure, names, numbers, terminology, speaker information, timing data, and the requirements of the destination format. Human review can be optional for low-risk use cases and targeted or mandatory when mistakes would create legal, clinical, compliance, accessibility, or editorial risk.
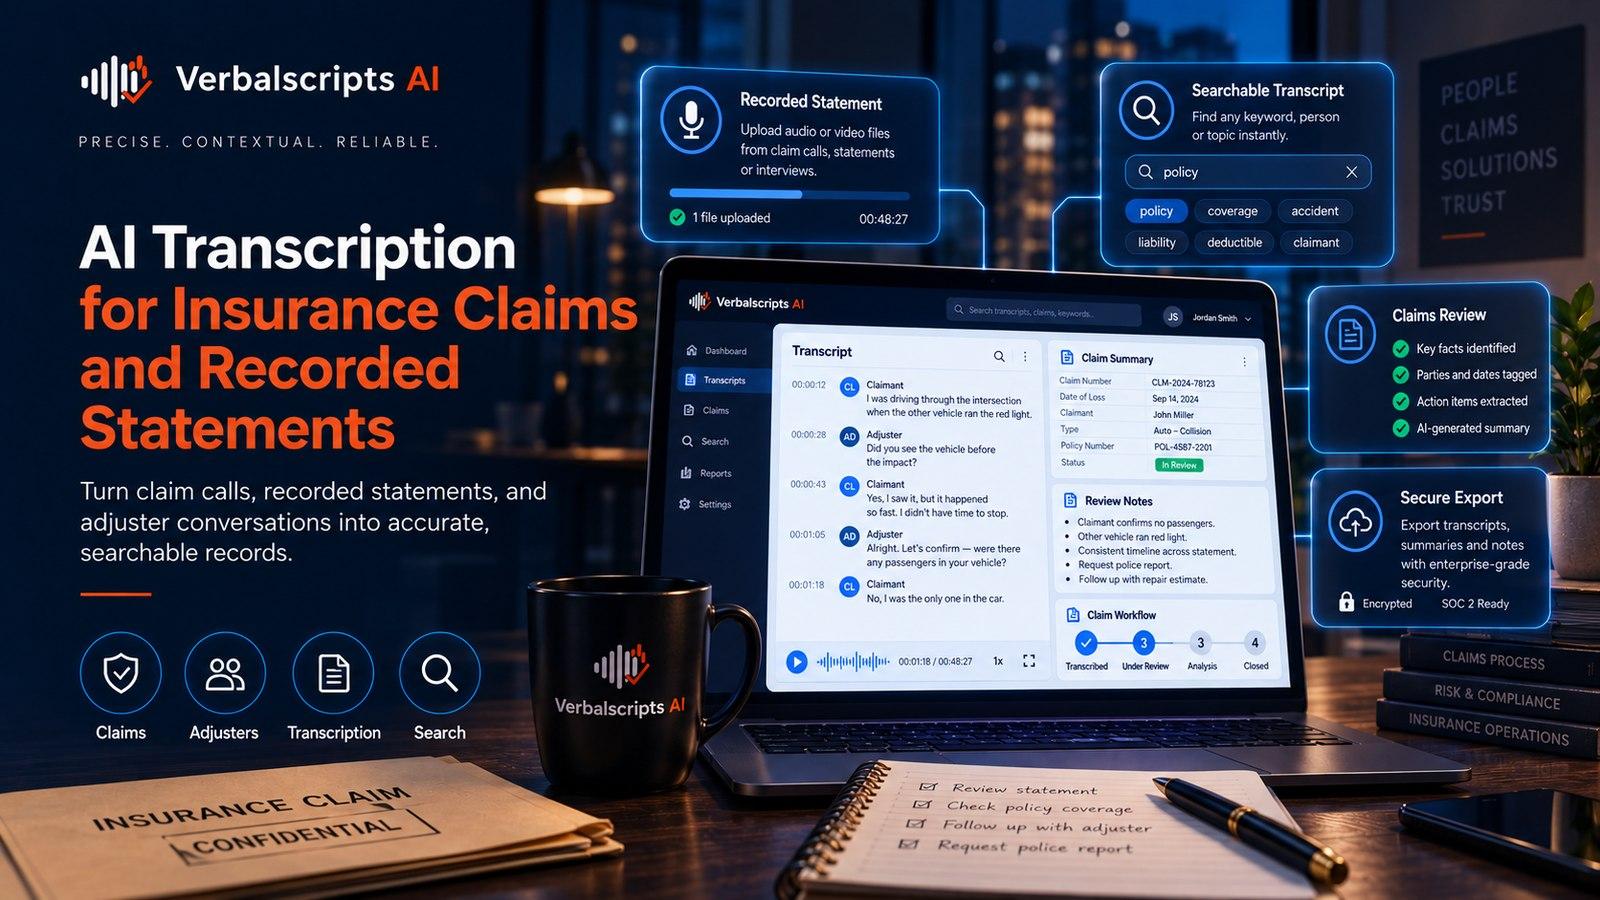
Insurance claim and recorded-statement transcription should preserve the sequence of questions and answers, dates, policy or claim terminology, names and descriptions without smoothing away uncertainty.
For financial institutions, insurers, compliance teams, risk teams, global communications teams, and regulated-service vendors, the question is not whether AI can produce text. It can. The operational question is whether the output preserves the parts people rely on (numbers and currencies, names and account or claim terminology, defined terms, speaker identity) and whether the workflow makes uncertainty, review and delivery rules explicit. A low-risk internal draft and a high-stakes final deliverable should not be forced through the same review path.
A strong implementation therefore combines fast automation with configurable review. Clients can choose AI-only output for speed-focused work, targeted human review for known risk areas, or full review when the intended use justifies it. The remainder of this guide shows how to make that choice and how to test the result.
Research-backed points to know
- SEC Rule 17a-4 electronic recordkeeping requirements include WORM preservation or an audit-trail alternative for broker-dealers that elect electronic recordkeeping.
- FINRA guidance notes retention obligations for business-related electronic communications under applicable books-and-records rules.
What matters most in ai transcription for insurance claims and recorded statements
Consider this production scenario: A recorded statement may include a claimant correcting a date later in the call; the transcript should preserve both the initial statement and correction.
Claimant, adjuster and witness roles. The workflow should make this explicit in the project specification. Where possible, preserve a direct link to the source so reviewers can verify difficult cases rather than infer from surrounding text. A good system also records recurring corrections so the same issue is less likely to reappear in later files.
Policy and coverage terminology. This is where generic language models often need domain or locale context. Use glossaries, participant lists, style guides, metadata, or structured constraints when available, but keep uncertainty visible when the source does not support a confident answer. Review effort should increase when an error here would change meaning or downstream decisions.
Dates, locations and damage descriptions. Quality control should separate this from general word accuracy. Create a dedicated check, sample it across easy and difficult source conditions, and track the correction rate over time. That makes it possible to improve the workflow instead of repeatedly fixing the same class of defect at delivery.
Background participants on recorded calls. Think about both correctness and usability. The text may be linguistically accurate yet still fail if this element is inconsistent, hard to trace, or incompatible with the destination format. The acceptance test should therefore reflect how the client will actually use the deliverable.
Redaction of personal identifiers when requested. This should be treated as a first-class requirement, not a cleanup item. Define the expected behavior before processing, give the AI and reviewer the relevant context, and add a QA check that can detect when the requirement is violated. For ai transcription for insurance claims and recorded statements, errors in this area can make an otherwise fluent output operationally misleading.
A production-ready workflow
Start with a project profile rather than a generic upload. Capture the content type, source language and locale, expected speakers or participants, required transcript style, output format, timestamp or timecode rules, glossary or spelling list, privacy constraints, and the selected review tier. If a client supplies a Word template, caption style guide, case caption, participant roster, terminology sheet, or previous accepted file, attach it to the job before the AI first pass.
The first pass should preserve stable structure. Audio/video is segmented with source-relative timing; documents keep paragraph or block identifiers; SRT/VTT workflows lock parser-sensitive fields. AI then produces transcription or translation with confidence and context signals where available. Mechanical QA catches missing segments, invalid timestamps, duplicate speakers, broken file syntax, or unfilled placeholders before a human spends time on the content.
Review is then routed by risk. AI-only delivery can remain available for speed-focused, lower-risk use cases. Targeted review can focus on low-confidence regions, names, numbers, terminology, or other high-impact elements. Full review is appropriate when the client's intended use requires it. After corrections, run a second mechanical validation, export from the approved version, and test the file in the destination application or player. For regulated records, the language platform should integrate with (rather than silently replace) the organization's system of record, retention policy, and audit requirements.
- Capture requirements and source context.
- Validate files and preserve stable identifiers.
- Run AI transcription/translation with project constraints.
- Run automated structural and entity checks.
- Route AI-only, targeted-review, or full-review path.
- Adjudicate uncertain/high-impact segments.
- Revalidate structure and destination format.
- Export approved version and apply retention/audit actions.
Human review: where it changes the outcome
Human review is most valuable when it is matched to the actual failure mode. A general proofreader may improve punctuation but miss a medical dosage, legal defined term, locale mismatch, or caption-timing problem. Reviewer assignment should therefore consider language, locale, domain expertise, and output type.
For this topic, the review queue should prioritize claimant, adjuster and witness roles, policy and coverage terminology, and dates, locations and damage descriptions. Those checks can be full-listen/full-read requirements for high-risk jobs or targeted checks for lower-risk jobs. The client should be able to select AI-only, targeted human review, or full review as separate service levels rather than receiving an unclear mixture.
Reviewer edits should be captured as structured feedback. Accepted names, terminology decisions, speaker identities, style choices, and recurring error patterns can be stored in a project profile or glossary. That makes later files more consistent and reduces repeated corrections without turning reviewer assumptions into unverified source text.
Quality assurance and measurable acceptance criteria
A useful quality program measures the errors that can actually damage the use case. Separate critical meaning errors from major usability errors and minor stylistic differences. Do not let a high overall word score hide a wrong name, number, speaker, dosage, defined term, timecode, or file structure.
For ai transcription for insurance claims and recorded statements, track at least claim-entity accuracy, Q/A attribution, and date/location accuracy. Add domain-wide checks for numbers and currencies, names and account or claim terminology, defined terms, speaker identity. Sample across languages, speakers, file lengths, and difficult source conditions rather than evaluating only clean material.
Quality metrics should feed operations. If one accent, language pair, reviewer, model configuration, or source type creates disproportionate corrections, change routing, preprocessing, glossary coverage, or reviewer calibration. The objective is not just to grade output; it is to reduce future error and rework.
A practical scorecard for this article:
| Metric | Why it matters |
|---|---|
| claim-entity accuracy | Captures a failure mode that generic word accuracy can hide |
| Q/A attribution | Tests whether the output remains operationally reliable |
| date/location accuracy | Measures the effectiveness of review and process control |
| Critical-error rate | Separates meaning-changing errors from minor style differences |
| Format/structure validation | Confirms the file works in the destination workflow |
Security, privacy and governance
A practical security baseline includes governed access, audit trails, immutable or reconstructable records where required, encryption, retention policies, vendor controls, and exportable logs. The workflow should map every copy of the source and output: upload, temporary chunks, AI draft, reviewer view, export, backup, and logs. Each copy needs a purpose, an access rule, and a retention decision.
Regulated recordkeeping can require more than confidentiality. SEC electronic recordkeeping rules for broker-dealers, for example, support WORM preservation or an audit-trail alternative that can recreate the original record if modified or deleted. A language-service platform should not be assumed to satisfy the organization's recordkeeping obligations; define which system owns the authoritative record and audit trail.
Common mistakes to avoid
- Optimizing for generic word accuracy while ignoring claim-entity accuracy.
- Failing to specify how claimant, adjuster and witness roles should be handled.
- Treating policy and coverage terminology as post-processing instead of part of the initial specification.
- Using only clean demo material instead of testing production conditions such as incorrect financial figures or policy details or speaker attribution errors.
- Allowing the system or reviewer to guess when the source is genuinely unclear.
- Delivering a file without testing it in the client's real template, player, editor, archive, or downstream system.
AI-only vs. human-reviewed: decision guide
| Situation | Suggested workflow |
|---|---|
| Clear source, internal search/discovery, low consequence of occasional errors | AI-only or light targeted review |
| Mostly clear source but high-value names, numbers, terminology, or selected segments | Targeted human review |
| External publication, accessibility deliverable, complex multilingual work | Native/domain review appropriate to the output |
| Legal, clinical, compliance, evidentiary, or otherwise high-consequence content | Strong human review aligned with governing requirements |
How Verbalscripts AI can support the workflow
Verbalscripts AI can support this as a configurable workflow rather than a one-size-fits-all transcript generator. A client uploads audio, video, text, or supported documents; selects the content type and language/locale; chooses output such as TXT, DOCX, PDF, SRT, VTT, or a custom template; and supplies instructions for names, spellings, speakers, terminology, formatting, or timestamps.
The AI first pass can be adapted around the risk points in this article, especially claimant, adjuster and witness roles, policy and coverage terminology, and dates, locations and damage descriptions: with automated structural validation before review. The client can keep the job AI-only or add targeted/full human review. For legal, medical, research, multilingual, media, or other specialist content, reviewer routing can be based on domain and locale rather than a generic proofreading queue.
The final deliverable should be generated only from an approved version, validated for its destination format, and accompanied by transparent status or limitations where needed. That combination (automation for scale, human judgment when selected, and format-aware QA) creates a more dependable language workflow than treating transcription or translation as a single model call.
Frequently asked questions
What is ai transcription for insurance claims and recorded statements?
Insurance claim and recorded-statement transcription should preserve the sequence of questions and answers, dates, policy or claim terminology, names and descriptions without smoothing away uncertainty.
Can AI-only output be used without human review?
Yes, when the client chooses AI-only service and the use case can tolerate the resulting risk. Clear internal meetings, search indexing, and early-stage research discovery are common examples. High-stakes legal, clinical, compliance, public-facing, or accessibility deliverables usually benefit from targeted or full human review.
What should human reviewers check first?
Start with high-impact entities and ambiguity: speaker identity, names, numbers, dates, terminology, negation, locale-sensitive wording, and any segment the model marks as uncertain. Then validate structure such as timestamps, cue boundaries, exhibits, headings, and file syntax.
How should accuracy be measured?
Use a use-case-specific rubric rather than one generic percentage. Separate critical meaning errors from major comprehension errors and minor style issues, and score structural requirements such as speakers, timecodes, terminology, and formatting independently.
What files can the workflow deliver?
Typical outputs include TXT, DOCX, PDF, CSV or JSON for structured workflows, and SRT or VTT for captions. The right format depends on the destination system and whether the client needs a custom template, timestamps, speaker labels, or bilingual layout.
What should a pilot for ai transcription for insurance claims and recorded statements include?
Use representative material that exposes the hard parts: claimant, adjuster and witness roles, policy and coverage terminology, and dates, locations and damage descriptions. Include the actual output format and score the pilot with metrics such as claim-entity accuracy, Q/A attribution, and date/location accuracy.
Key takeaways
Key takeaways
- ai transcription for insurance claims and recorded statements should be designed as an end-to-end process, not a one-click model output.
- The highest-value controls are the ones that protect claimant, adjuster and witness roles, policy and coverage terminology, and dates, locations and damage descriptions.
- Preserve source traceability and parser-sensitive structure before changing text or language.
- Make AI-only, targeted human review, and full human review explicit service choices.
- Track claim-entity accuracy, Q/A attribution, and date/location accuracy instead of relying on one generic accuracy claim.
- Test the final deliverable in the client’s actual system, template, player, or publishing workflow.
Sources and further reading
**Editorial note:** This article provides general workflow guidance, not legal, medical, regulatory, financial, or accessibility compliance advice. Requirements vary by jurisdiction, organization, platform, and use case.