AI can make AI transcription API dramatically faster, but speed only creates value when the output remains trustworthy in context. A transcript may be linguistically readable yet unusable for coding; a translation may be fluent yet wrong on one critical term; an API may be fast yet difficult to operate safely at scale.
The central problem is turning model capability into a dependable service boundary. Enterprise systems must handle partial failure, sensitive payloads, authorization, versioning, observability and quality evidence. For AI transcription API, two controls (authentication and authorization; and asynchronous job lifecycle) should be visible in the API contract and operational runbook.
Quick answer
A production transcription API should define authentication, job states, idempotency behavior, rate limits, retry semantics, webhook verification, output schemas, data retention, model/version behavior and error contracts (not only an upload endpoint. The central problem is turning model capability into a dependable service boundary. Enterprise systems must handle partial failure, sensitive payloads, authorization, versioning, observability and quality evidence. For AI transcription API, two controls) authentication and authorization; and asynchronous job lifecycle, should be visible in the API contract and operational runbook.
What buyers are actually evaluating
For AI transcription API, treat the production layer as an integration surface around a language-processing capability. The design needs a contract for inputs, authentication, job states, outputs, failures, retention and versioning. Callers should not need to know model internals to use the service safely, while operators still retain enough provenance to debug and audit it. The contract should make authentication and authorization explicit.
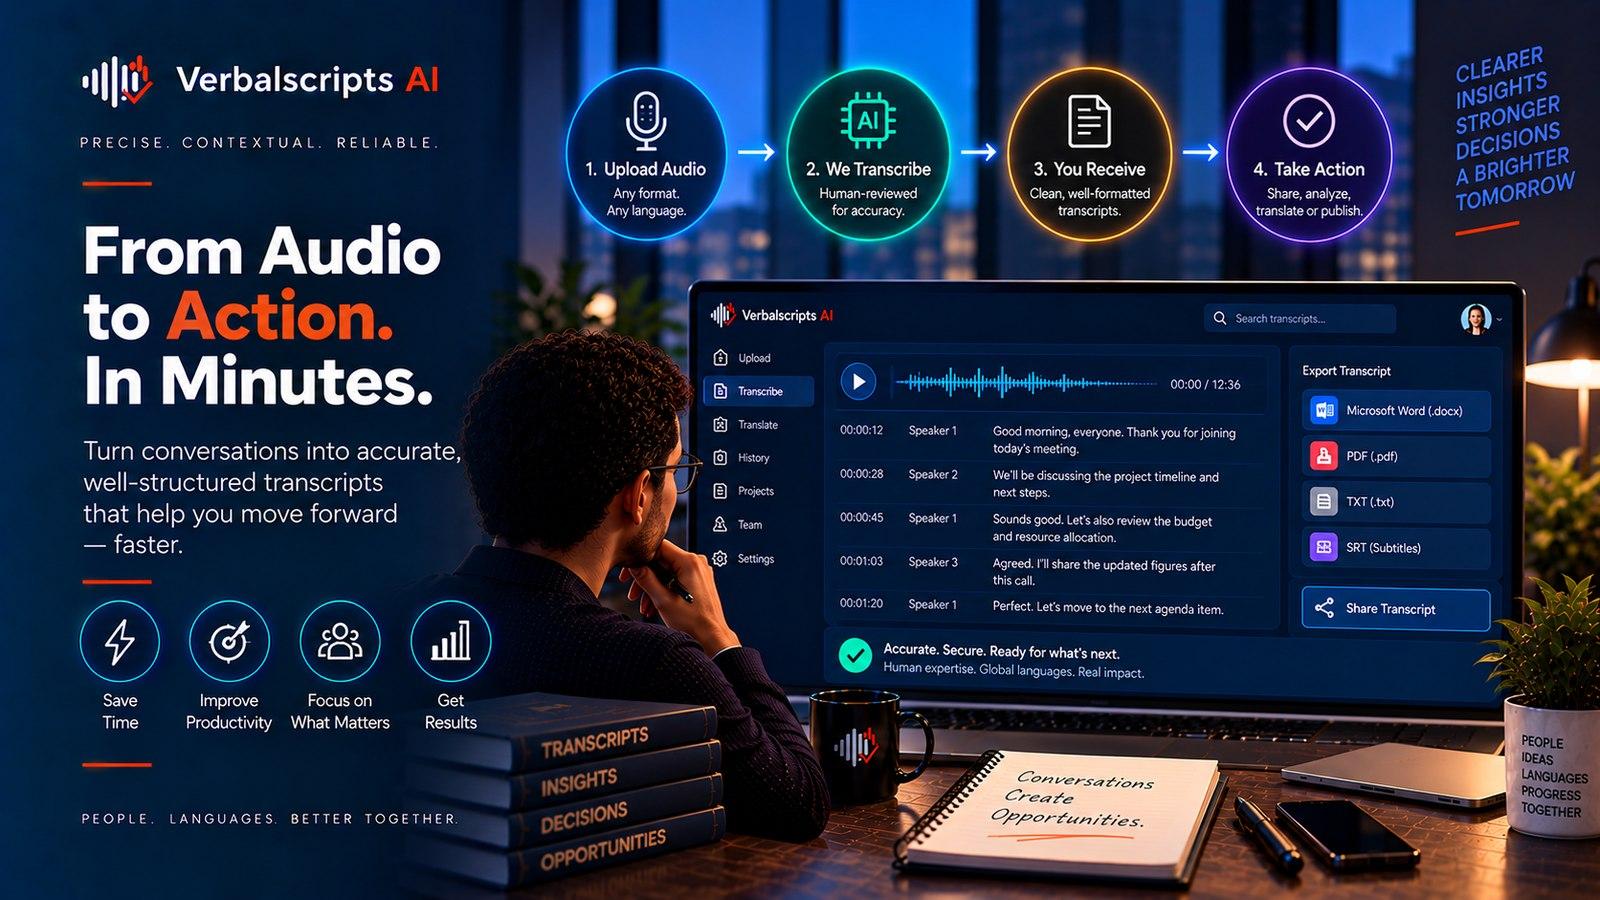
For large files and variable processing times in AI transcription API, asynchronous job patterns are usually easier to operate than keeping one HTTP request open. The client submits work, receives a job identifier, polls or listens for events, retrieves results, and handles retries according to documented idempotency and error rules. Design that state machine with asynchronous job lifecycle in mind rather than adding it after launch.
Why the hard cases matter
OWASP’s API Security Top 10 for 2023 emphasizes authorization, authentication, excessive exposure of object properties, resource consumption, security misconfiguration and unsafe API consumption. A language API that processes sensitive audio or documents inherits the same API-security concerns as any other production service.
The practical edge cases in AI transcription API are predictable, but they are not all equally important. Start with two priority areas (authentication and authorization; and asynchronous job lifecycle) then add cases where context is sparse, the source is noisy or ambiguous, or an automated result triggers a downstream action. Instead of averaging those failures away, make them explicit in the test plan and assign an owner for each exception path.
The quality dimensions to design for
1. Authentication and authorization
Treat authentication and authorization as a design decision within AI transcription API. Write the requirement in operational terms, attach positive and negative examples, and test it on representative content before scaling. Record not only whether an output passed but why it failed, because recurring error categories are more actionable than one average score. Where the requirement is high risk, add a second source of evidence such as human review, a reference list or a targeted validation rule.
2. Asynchronous job lifecycle
Treat asynchronous job lifecycle as part of the operational layer around AI transcription API, not merely a model parameter. Production workflows need explicit job IDs, states, retries, timeouts and ownership of failures. Persist enough metadata to reproduce what happened (input version, language settings, model or workflow version, timestamps and review status) without retaining sensitive payloads longer than necessary. Design for partial failure: a callback may be duplicated, a file may be unreadable, or one item in a batch may fail while others succeed.
3. File upload and storage patterns
Treat file upload and storage patterns as a design decision within AI transcription API. Write the requirement in operational terms, attach positive and negative examples, and test it on representative content before scaling. Record not only whether an output passed but why it failed, because recurring error categories are more actionable than one average score. Where the requirement is high risk, add a second source of evidence such as human review, a reference list or a targeted validation rule.
4. Webhooks and polling
Treat webhooks and polling as part of the operational layer around AI transcription API, not merely a model parameter. Production workflows need explicit job IDs, states, retries, timeouts and ownership of failures. Persist enough metadata to reproduce what happened (input version, language settings, model or workflow version, timestamps and review status) without retaining sensitive payloads longer than necessary. Design for partial failure: a callback may be duplicated, a file may be unreadable, or one item in a batch may fail while others succeed.
5. Output schemas and timestamps
Use output schemas and timestamps to create a reversible path from the output back to source evidence in AI transcription API. The useful granularity depends on the task: research coding may need timestamps at speaker turns or regular intervals, while subtitle and media workflows may need segment-level timing. Generate timecodes from the same media version used for review; edits that change media duration can invalidate them. Consistent timestamps make quote verification, adjudication and targeted re-listening far faster than manually searching a long recording.
A practical production workflow
Step 1: Define the API contract
Specify authentication, endpoints, payload limits, job states, output schemas, errors, version behavior, rate limits and retention. For AI transcription API, this step should explicitly verify authentication and authorization. Record the decision in project metadata so later reviewers can reproduce the same rule.
Step 2: Separate upload from processing
Use secure object access or multipart upload for large payloads, then submit a lightweight job referencing the accepted asset. For AI transcription API, this step should explicitly verify asynchronous job lifecycle.
Step 3: Make jobs idempotent and observable
Assign stable job IDs and idempotency keys, log state transitions and expose enough metadata for callers to reconcile retries safely. For AI transcription API, this step should explicitly verify file upload and storage patterns.
Step 4: Process asynchronously
Queue work, control concurrency and isolate failures so one bad file does not block an entire batch. For AI transcription API, this step should explicitly verify webhooks and polling. Record the decision in project metadata so later reviewers can reproduce the same rule.
Step 5: Validate and quality-gate outputs
Run schema checks, language/format checks and any human review required before marking results final. For AI transcription API, this step should explicitly verify output schemas and timestamps.
Step 6: Deliver with verifiable events
Sign webhooks, tolerate duplicate delivery, support polling as a fallback and retain an audit trail for final retrieval and deletion. For AI transcription API, this step should explicitly verify rate limits, retries and observability.
How to evaluate quality
Measure AI transcription API across reliability, security and language quality. Operational metrics include job success rate, queue time, processing latency, retry rate and webhook delivery; language metrics include error rate, critical-term accuracy and review effort; security evidence includes access and audit behavior under the documented threat model.
Define service-level objectives on end-to-end accepted output rather than model runtime alone. A job that finishes inference quickly but spends hours in retry loops or produces malformed output has not met the user’s objective. Test two areas explicitly: authentication and authorization; and asynchronous job lifecycle.
- Measure or review authentication and authorization; define the unit, source of truth and pass/fail rule before scoring.
- Measure or review asynchronous job lifecycle; define the unit, source of truth and pass/fail rule before scoring.
- Measure or review file upload and storage patterns; define the unit, source of truth and pass/fail rule before scoring.
- Measure or review webhooks and polling; define the unit, source of truth and pass/fail rule before scoring.
- Measure or review output schemas and timestamps; define the unit, source of truth and pass/fail rule before scoring.
Privacy, governance and operational controls
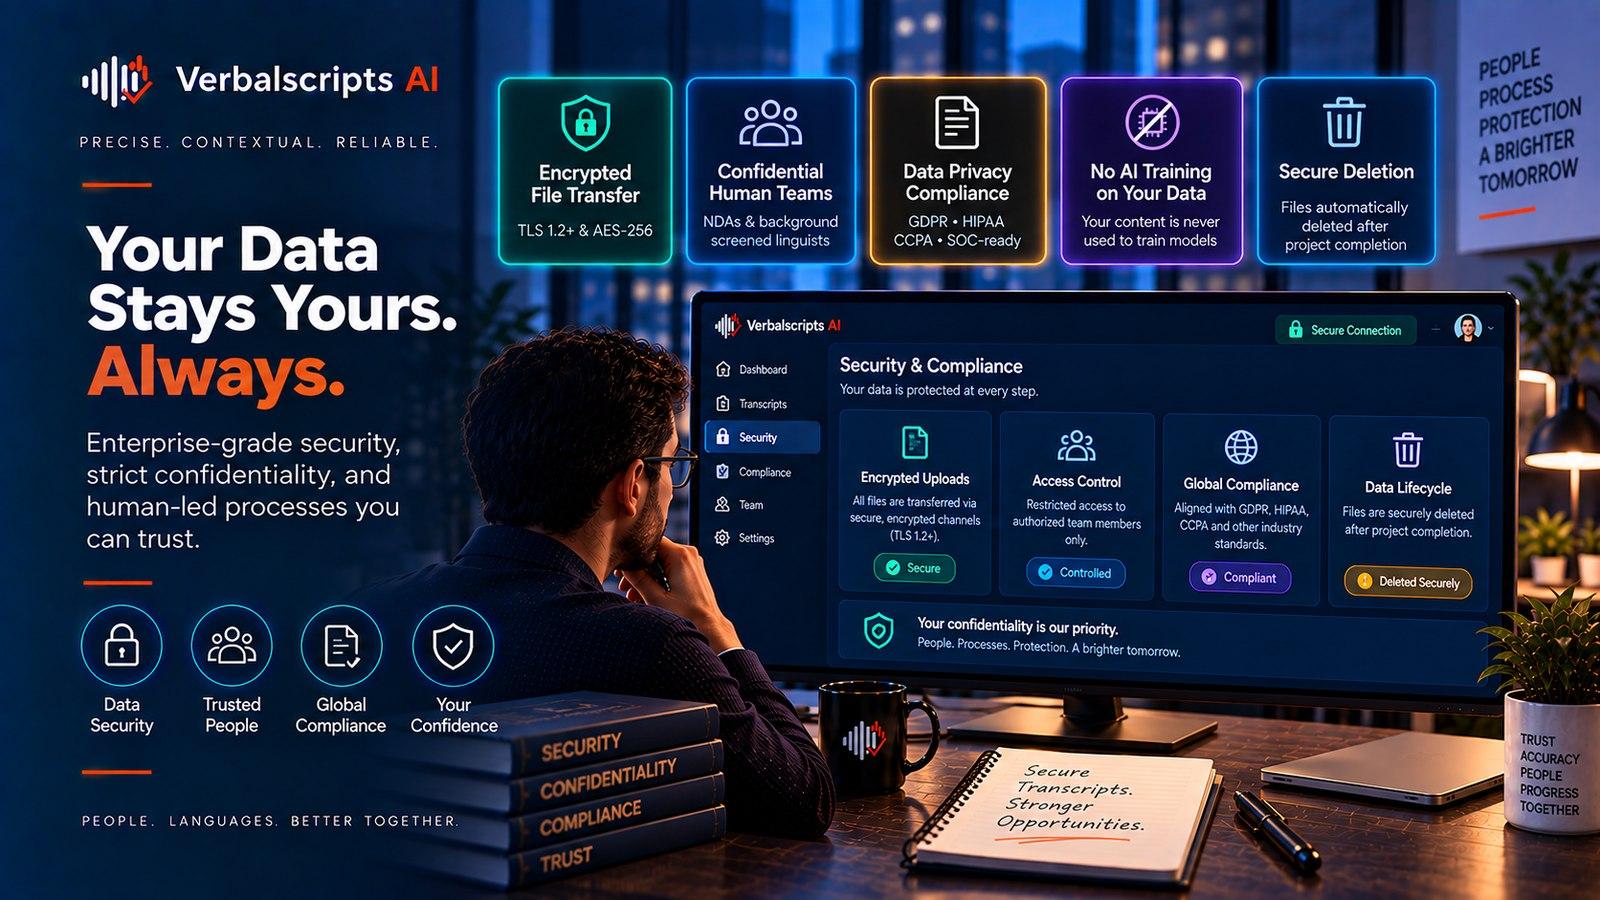
For AI transcription API, operational controls for authentication and authorization, as well as asynchronous job lifecycle, should be reviewed with the security model. Enterprise language APIs should treat audio, documents and translated output as sensitive application data. Use strong authentication, object- and function-level authorization, encrypted transport, minimal response fields, rate/resource controls and secure secret management. Do not place long-lived credentials or sensitive payloads in webhook URLs or logs.
Retention and deletion for AI transcription API need the same engineering rigor as processing. Define when uploads, intermediate files, transcripts, translations, logs and backups age out; make client-facing deletion semantics clear; and document any exceptions required for security or audit. Include authentication and authorization in runbooks so an operational incident can be reconciled to the correct data lifecycle.
Common failure patterns
- Treating authentication and authorization as an informal preference instead of a testable requirement with examples and ownership.
- Designing only the happy path and discovering during production that retries create duplicate jobs or missing state transitions.
- Treating file upload and storage patterns as an informal preference instead of a testable requirement with examples and ownership.
- Generating timestamps once, editing or replacing the media, and then publishing timecodes that no longer point to the same evidence.
- Changing normalization, formatting or review rules mid-project without versioning the benchmark or output specification.
- Scaling volume before measuring rework and exception rates on a representative pilot.
A good corrective action for AI transcription API changes the system, not only the current file. If the failure involved authentication and authorization or asynchronous job lifecycle, update the relevant guideline, reference data, validation rule, routing logic or evaluation set so the same class of error is easier to detect next time.
Implementation checklist
- ☐ Write the intended use, target users and unacceptable error types.
- ☐ Use representative inputs rather than only clean demonstration files.
- ☐ Define API auth, payload, job-state, schema, versioning and error-contract requirements.
- ☐ Choose automatic metrics and human review rules that match the deliverable.
- ☐ Document privacy, retention, access, consent or licensing obligations.
- ☐ Preserve version, provenance and source links needed for audit or correction.
Advanced implementation considerations
Design the benchmark before optimizing the system
It is tempting to tune AI transcription API against whatever data is easiest to obtain. That reverses the logic. First write the deployment population and failure costs, then build a benchmark that represents them. If the benchmark changes every time the model changes, improvement cannot be distinguished from a moving test. Keep one stable regression set and a separate challenge set for newly discovered edge cases.
Separate confidence from correctness
In AI transcription API, model confidence can help prioritize review, but confidence scores are not automatically calibrated probabilities of correctness. Validate how confidence relates to actual error on your data and on important slices. A high-confidence wrong name or speaker label can be more damaging than a low-confidence harmless filler. Use confidence for routing only after demonstrating that the thresholds behave predictably.
Track correction effort as a product metric
For AI transcription API, automatic scores describe output similarity; they do not directly describe the labor required to make a deliverable acceptable. Measure review minutes per audio minute, edits per thousand words, escalation rate, or another operational measure that fits the workflow. When two systems have similar accuracy, the one that produces easier-to-review structure can have substantially lower total cost.
Version instructions and reference data
In AI transcription API, prompts, style guides, glossaries, speaker rosters, annotation rules and normalization code are part of the effective model. Store their versions with the job or dataset. When quality shifts, operators should be able to tell whether the change came from the model, the input mix, the instructions, or human review behavior.
- ☐ Run a pilot, measure rework and exceptions, then scale only after the acceptance criteria are met.
Frequently asked questions
What should buyers test first for AI transcription API?
For AI transcription API, use representative files and require the vendor to process them through the actual production workflow, including formatting, review and delivery rather than a hand-picked model demo.
Which quality metric should be in the contract?
For AI transcription API, use metrics tied to the deliverable: WER or entity/speaker measures for ASR, analytic error/severity criteria for translation, plus critical-error rules and rework expectations.
What security evidence should be requested?
For AI transcription API, ask about access controls, encryption, retention, subprocessors, incident response, auditability and relevant independent assurance or regulatory agreements for your data type.
How should human review be priced?
For AI transcription API, clarify whether review is full-file or sampled, what reviewer competence is required, what counts as rework and whether escalation or specialist review is included.
How do you compare vendors fairly?
For AI transcription API, give them the same inputs, references, terminology, output specification and scoring method. Compare delivered quality, turnaround, exceptions and operational fit on equal conditions.
Conclusion
AI Transcription API: A Buyer and Developer Guide is most useful when it is treated as a measurable workflow rather than a feature checkbox. Define the source of truth, preserve the context that the next step needs, test the hard cases, and make review depth proportional to risk. The result is faster automation without sacrificing traceability or quality discipline. For Verbalscripts AI, the practical objective is a language-data pipeline that can move from AI speed to human-reviewed reliability when the project requires it, while keeping output structured enough for research, product and enterprise systems.
Research references
- OWASP API Security Top 10, 2023: https://owasp.org/API-Security/editions/2023/en/0x11-t10/
- NIST AI Risk Management Framework 1.0: https://www.nist.gov/itl/ai-risk-management-framework
- NIST Privacy Framework: https://www.nist.gov/privacy-framework
- ISO/IEC 27001:2022: Information security management systems: https://www.iso.org/standard/27001
- AICPA, Trust Services Criteria: https://www.aicpa-cima.com/resources/download/2017-trust-services-criteria-with-revised-points-of-focus-2022