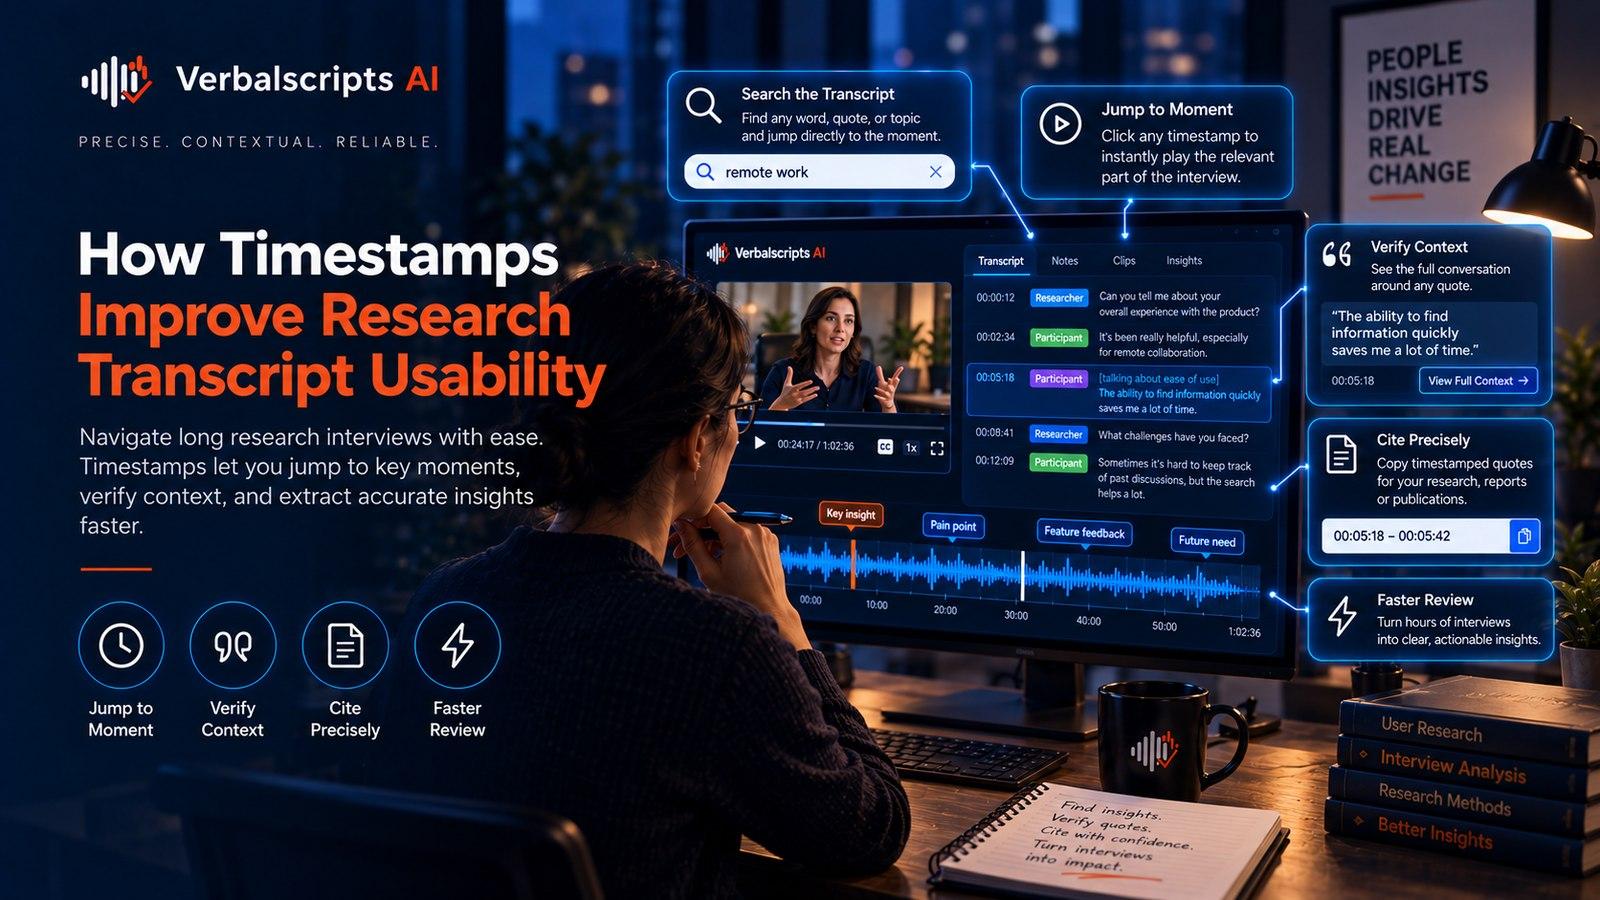
AI Academic Research Transcription: Privacy, Formatting and Review is increasingly relevant to researchers, research operations teams, universities, archives and qualitative analysts because speech and multilingual content are no longer side files; they feed research analysis, product decisions and operational systems. The useful question is not simply whether AI can produce text. It is whether the output is accurate enough, structured enough and governed well enough for the next step.
The central problem is that a transcript becomes part of the research record. Errors can change a quotation, blur who said what, break the chain back to the recording, or introduce disclosure risk. For AI academic research transcription, the specification should therefore make two requirements explicit: institutional privacy and research ethics; and pseudonymisation and anonymisation rather than leaving them to each transcriber.
Quick answer
AI Academic Research Transcription works best when teams define the intended use first, provide representative data and context, measure the specific errors that matter, and route uncertain or high-risk output to qualified human review. The best system is not the one with the strongest generic benchmark; it is the one whose measured behavior matches the deployment conditions and acceptance criteria.
What AI Academic Research Transcription means in practice
In AI academic research transcription, recorded or multilingual participant material becomes a textual research artifact that may later be coded, quoted, shared, archived or translated. Because each use imposes different requirements, researchers should decide the transcription convention before collection begins rather than treating it as clerical cleanup after interviews are complete. The specification for this article starts with institutional privacy and research ethics.
The textual record produced by AI academic research transcription is not a neutral copy operation. Decisions about fillers, pauses, dialect, nonverbal events, anonymisation and translation can shape what analysts notice. The most defensible workflow documents those decisions and preserves a path back to source audio for passages that matter, with pseudonymisation and anonymisation treated as a reproducible rule rather than an informal preference.
Why the hard cases matter
The Oral History Association’s archival guidance notes that automated transcription can be useful as a rough first draft, but recommends review because both human and automated transcription can be fallible. It also highlights transcripts and time-tagged indexes as tools for discoverability and access.
The practical edge cases in AI academic research transcription are predictable, but they are not all equally important. Start with two priority areas (institutional privacy and research ethics; and pseudonymisation and anonymisation) then add cases where context is sparse, the source is noisy or ambiguous, or an automated result triggers a downstream action. Instead of averaging those failures away, make them explicit in the test plan and assign an owner for each exception path.
The quality dimensions to design for
1. Institutional privacy and research ethics
Design institutional privacy and research ethics before data enters the AI academic research transcription workflow, not after the system is live. Define who may access source files, what the provider may do with them, how long each artifact is retained, whether data can be used for model improvement, and how deletion is verified. Separate identity metadata from transcript content where practical, restrict reviewer access to the minimum needed, and keep an auditable record of sensitive-data handling. Accuracy does not compensate for a workflow that violates the project’s consent or governance conditions.
2. Pseudonymisation and anonymisation
Treat pseudonymisation and anonymisation as a design decision within AI academic research transcription. Write the requirement in operational terms, attach positive and negative examples, and test it on representative content before scaling. Record not only whether an output passed but why it failed, because recurring error categories are more actionable than one average score. Where the requirement is high risk, add a second source of evidence such as human review, a reference list or a targeted validation rule.
3. Uniform transcript formatting
Specify uniform transcript formatting so the output of AI academic research transcription can be used without a second manual production step. Define headings, speaker labels, paragraphing, lists, timestamps, tables and non-speech notation before processing. For translated documents, structure and markup must survive language expansion and reordering. Validate the final DOCX, PDF, subtitle or structured JSON output, not just the raw text returned by a model.
4. Confidential handling by vendors and reviewers
Design confidential handling by vendors and reviewers before data enters the AI academic research transcription workflow, not after the system is live. Define who may access source files, what the provider may do with them, how long each artifact is retained, whether data can be used for model improvement, and how deletion is verified. Separate identity metadata from transcript content where practical, restrict reviewer access to the minimum needed, and keep an auditable record of sensitive-data handling. Accuracy does not compensate for a workflow that violates the project’s consent or governance conditions.
5. Retention and deletion rules
Design retention and deletion rules before data enters the AI academic research transcription workflow, not after the system is live. Define who may access source files, what the provider may do with them, how long each artifact is retained, whether data can be used for model improvement, and how deletion is verified. Separate identity metadata from transcript content where practical, restrict reviewer access to the minimum needed, and keep an auditable record of sensitive-data handling. Accuracy does not compensate for a workflow that violates the project’s consent or governance conditions.
A practical production workflow
Step 1: Define the research transcription convention
Decide verbatim level, speaker-label style, timestamps, treatment of fillers and nonverbal events, anonymisation policy and the intended analysis or archive format. For AI academic research transcription, this step should explicitly verify institutional privacy and research ethics. Record the decision in project metadata so later reviewers can reproduce the same rule.
Step 2: Prepare source and context
Use the best available audio and provide participant IDs, interview guides, place/name spellings, terminology and field notes that legitimately help resolve ambiguity. For AI academic research transcription, this step should explicitly verify pseudonymisation and anonymisation.
Step 3: Generate the AI draft
Process the recording with language, locale and speaker settings appropriate to the study. Preserve time alignment and raw output for traceability. For AI academic research transcription, this step should explicitly verify uniform transcript formatting.
Step 4: Review against the recording
Correct wording, speaker attribution and critical references. Mark unresolved audio explicitly instead of inventing certainty. For AI academic research transcription, this step should explicitly verify confidential handling by vendors and reviewers. Record the decision in project metadata so later reviewers can reproduce the same rule.
Step 5: Apply privacy and formatting rules
De-identify according to the research plan, normalize headings and speaker turns, and keep pseudonyms consistent across files. For AI academic research transcription, this step should explicitly verify retention and deletion rules.
Step 6: Validate for coding or deposit
Open the final file in the analysis or archive workflow, confirm stable IDs and timestamps, and retain a controlled version history. For AI academic research transcription, this step should explicitly verify documented human review.
How to evaluate quality
Measure AI academic research transcription at the unit that drives business or research decisions. Track both average quality and critical exceptions, because a small number of wrong names, roles or commitments can dominate user impact.
Keep a sample of human-verified outputs as a regression set and update it deliberately when the product’s population, language mix or content changes.
- Measure or review institutional privacy and research ethics; define the unit, source of truth and pass/fail rule before scoring.
- Measure or review pseudonymisation and anonymisation; define the unit, source of truth and pass/fail rule before scoring.
- Measure or review uniform transcript formatting; define the unit, source of truth and pass/fail rule before scoring.
- Measure or review confidential handling by vendors and reviewers; define the unit, source of truth and pass/fail rule before scoring.
- Measure or review retention and deletion rules; define the unit, source of truth and pass/fail rule before scoring.
Privacy, governance and operational controls
Research audio and transcripts used in AI academic research transcription can contain direct identifiers, indirect identifiers and sensitive context. Apply data minimisation: collect and share only what the project requires, separate identity keys from analysis files where practical, and control access to raw recordings more tightly than derived anonymised text. Review anonymisation in context because combinations of place, occupation, family detail or rare events can re-identify a participant even after a name is replaced. For this workflow, pay particular attention to institutional privacy and research ethics.
Document who performed transcription and review for AI academic research transcription, which version of the audio was used, and what editorial transformations were applied. Provenance becomes especially important when the study depends on pseudonymisation and anonymisation, because a challenged quotation or deposited dataset should be traceable to the applicable source and convention.
Common failure patterns
- Sending sensitive source material through a workflow whose retention, reuse or reviewer access rules are not documented.
- Treating pseudonymisation and anonymisation as an informal preference instead of a testable requirement with examples and ownership.
- Treating uniform transcript formatting as an informal preference instead of a testable requirement with examples and ownership.
- Treating confidential handling by vendors and reviewers as an informal preference instead of a testable requirement with examples and ownership.
- Treating retention and deletion rules as an informal preference instead of a testable requirement with examples and ownership.
A good corrective action for AI academic research transcription changes the system, not only the current file. If the failure involved institutional privacy and research ethics or pseudonymisation and anonymisation, update the relevant guideline, reference data, validation rule, routing logic or evaluation set so the same class of error is easier to detect next time.
Implementation checklist
- ☐ Write the intended use, target users and unacceptable error types.
- ☐ Use representative inputs rather than only clean demonstration files.
- ☐ Define language, locale, speaker, formatting and terminology requirements.
- ☐ Choose automatic metrics and human review rules that match the deliverable.
- ☐ Document privacy, retention, access, consent or licensing obligations.
- ☐ Preserve version, provenance and source links needed for audit or correction.
Advanced implementation considerations
Design the benchmark before optimizing the system
It is tempting to tune AI academic research transcription against whatever data is easiest to obtain. That reverses the logic. First write the deployment population and failure costs, then build a benchmark that represents them. If the benchmark changes every time the model changes, improvement cannot be distinguished from a moving test. Keep one stable regression set and a separate challenge set for newly discovered edge cases.
Separate confidence from correctness
In AI academic research transcription, model confidence can help prioritize review, but confidence scores are not automatically calibrated probabilities of correctness. Validate how confidence relates to actual error on your data and on important slices. A high-confidence wrong name or speaker label can be more damaging than a low-confidence harmless filler. Use confidence for routing only after demonstrating that the thresholds behave predictably.
Track correction effort as a product metric
For AI academic research transcription, automatic scores describe output similarity; they do not directly describe the labor required to make a deliverable acceptable. Measure review minutes per audio minute, edits per thousand words, escalation rate, or another operational measure that fits the workflow. When two systems have similar accuracy, the one that produces easier-to-review structure can have substantially lower total cost.
Version instructions and reference data
In AI academic research transcription, prompts, style guides, glossaries, speaker rosters, annotation rules and normalization code are part of the effective model. Store their versions with the job or dataset. When quality shifts, operators should be able to tell whether the change came from the model, the input mix, the instructions, or human review behavior.
- ☐ Run a pilot, measure rework and exceptions, then scale only after the acceptance criteria are met.
Frequently asked questions
What is the main benefit of AI academic research transcription?
For AI academic research transcription, it reduces the manual effort required to convert spoken or multilingual content into structured, searchable and reviewable text while preserving a path back to source evidence.
What affects accuracy most?
For AI academic research transcription, source quality, language and domain coverage, speaker variation, terminology, context, model selection and the amount and competence of human review all affect delivered accuracy.
Should AI output be reviewed?
For AI academic research transcription, review depth should match risk. High-stakes, public-facing, research-critical or system-of-record content deserves stronger source-grounded review than low-risk internal drafts.
How should privacy be handled?
For AI academic research transcription, define permitted use, access, retention and deletion before upload, then enforce least privilege and data minimisation through the workflow.
How do teams improve quality over time?
For AI academic research transcription, capture corrections and error categories, analyze recurring failures, update reference materials or datasets, and re-run a stable benchmark after each material workflow change.
Conclusion
AI Academic Research Transcription: Privacy, Formatting and Review is most useful when it is treated as a measurable workflow rather than a feature checkbox. Define the source of truth, preserve the context that the next step needs, test the hard cases, and make review depth proportional to risk. The result is faster automation without sacrificing traceability or quality discipline. For Verbalscripts AI, the practical objective is a language-data pipeline that can move from AI speed to human-reviewed reliability when the project requires it, while keeping output structured enough for research, product and enterprise systems.
Research references
- Oral History Association, Principles and Best Practices: https://oralhistory.org/principles-and-best-practices-revised-2018/
- Oral History Association, Archiving Oral History: Manual of Best Practices: https://oralhistory.org/archives-principles-and-best-practices-complete-manual/
- UK Data Service, Managing data: tools and templates: https://ukdataservice.ac.uk/learning-hub/teach-with-real-data/teaching-resources-data-management/managing-data-tools-and-templates/
- UK Data Service, Prepare your data collection for deposit: https://ukdataservice.ac.uk/help/deposit-data/prepare-your-data-for-deposit/
- Braun & Clarke (2006), Using thematic analysis in psychology: https://doi.org/10.1191/1478088706qp063oa
- van Nes et al. (2010), Language differences in qualitative research: is meaning lost in translation?: https://doi.org/10.1007/s10433-010-0168-y